


Chapter 10 of 13 · Toolkit, any time · About 15 minutes
Compare your results with outside data: live queries and public datasets
Your own numbers tell you what happened in your program. A board or funder often asks the next question: compared with what? The answer sits in other systems, like your CRM, and in public datasets from the Bureau of Labor Statistics, the Department of Labor and the IRS.
You will learn: when to query outside data live and when to load it once, how to match definitions before you compare, how to keep names out, and which public sources to trust for wages, employer records and charity finances.
Who this is for: both roads. Funders who want a fair outside number beside a partner's results, and funded partners whose employer or applicant records sit in another system. Use it any time after your data dictionary is written, and bring one question your own records cannot answer.
On this page: Two ways · What MCP is · Match definitions first · The wage example · Keep names out · Sources · Limits · Try it · Questions
What are the two ways to bring outside data into your reporting?
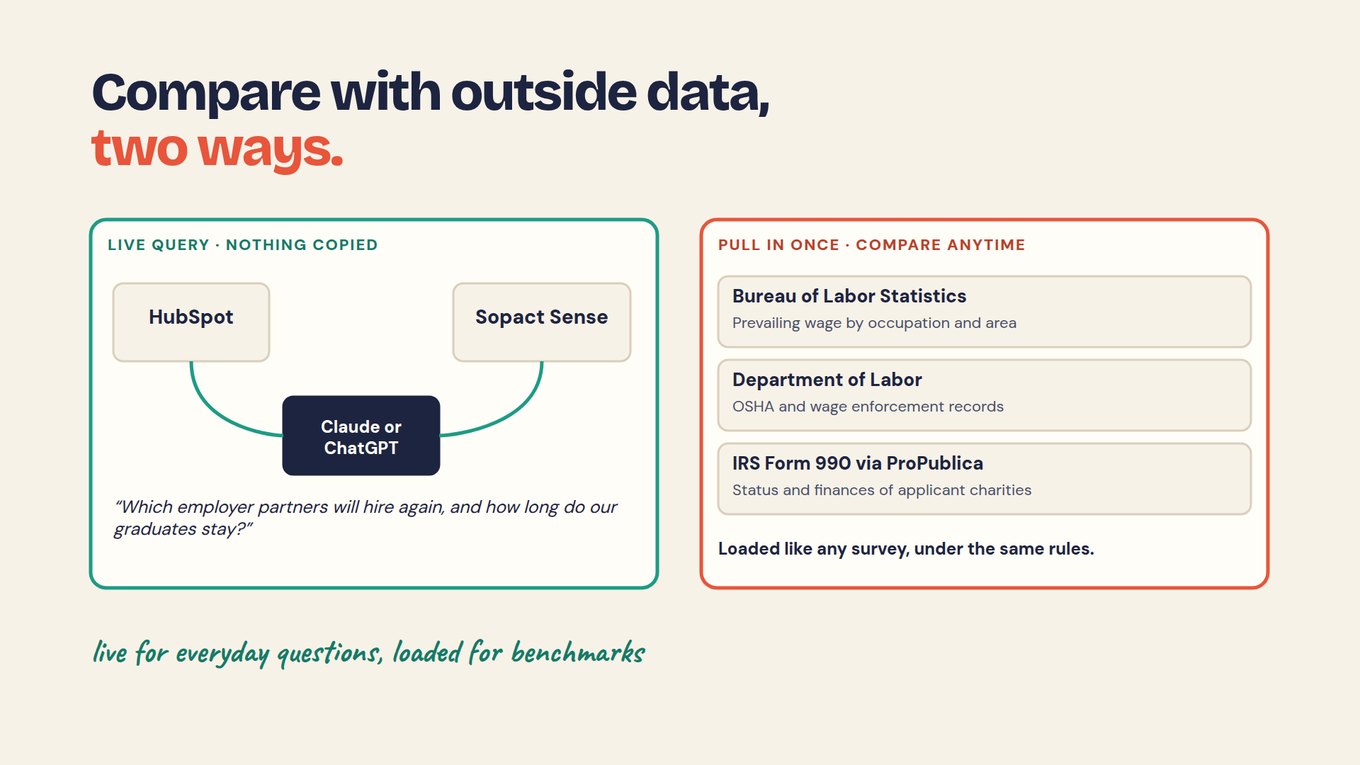
In short: query it live, where it already sits, or load it once as a fixed reference. Live suits everyday questions whose answer changes every week. Loading once suits benchmarks and compliance checks that everyone must read from the same file.
Questions you ask often, answered from today's records: "Which employer partners will hire again, and how long do our graduates stay?" Employer history comes from HubSpot, placement and retention from Sopact Sense.
Benchmarks and checks you must repeat and cite: Bureau of Labor Statistics wages, Department of Labor enforcement records, IRS Form 990 filings of charities that apply to you.
What is MCP, in plain terms?
In short: MCP, the Model Context Protocol, is a shared way for an AI assistant to ask questions of another system's data. The data stays in that system; the assistant reads back the answer.
Each system that supports MCP offers a connector, and you approve which ones your assistant may use. Anthropic published MCP as an open standard in 2024, and Claude and ChatGPT both use it. HubSpot offers a connector, and Claude or ChatGPT can query Sopact Sense data the same way.
The weak point is the join. The assistant must match an employer in HubSpot to the same employer in your placement records, so agree one spelling, or better, one employer ID in both systems.
A Sopact demo with a fictional workforce program and demo data. Watch HubSpot employer partners and Sopact data queried together in Claude through MCP, then Bureau of Labor Statistics wages, Department of Labor records and IRS 990 data via ProPublica brought in to check grant applicants. Watch on YouTube ↗
Why must definitions match before you compare?
In short: a comparison is only fair when both numbers count the same thing, for the same people, place and period. Write both definitions in one row first.
Outside sources define things their own way. A wage estimate may cover every worker in a job, not new hires; a public placement rate may use a different window after exit. It is the same discipline as checking a partner's report against the agreement: when Partner C counted placements within six months instead of 90 days, the fund held its number back. Treat an outside figure the same way.
How do you compare starting wages with the local wage for the same job?
In short: match each training track to an occupation code, pick the wage estimate for the same area and year, and compare hourly with hourly. Compare new graduates with the lower end of the local range, not only the median.
The fictional workforce fund's agreement asks for starting wage, hourly, by track. Each track trains for a job with a Standard Occupational Classification (SOC) code; a medical assistant track, for example, maps to SOC 31-9092. The Bureau of Labor Statistics publishes hourly wages for that code by state and metropolitan area.
New hires usually start below the median for everyone in the job, so show the 25th percentile beside the median.
ONE MATCHED COMPARISON · FICTIONAL EXAMPLE
Partner C's single average wage cannot enter this comparison: it mixes tracks. That is why "Can you split starting wage by track?" was one of the fund's three questions.
How do you keep names out when you connect outside data?
In short: compare on groups and codes, never on people. A wage benchmark needs a track and an area, not a name, so choose the fields an AI tool may see before you ask anything.
Public data describes occupations, employers and organizations, so it needs no person's name. Your records hold names and emails; send counts, tracks, wages and dates instead. A live query sends the AI tool whatever it returns, so the same rule applies.
In Sopact Sense today, field selection lets you choose which fields are sent to AI and keep names and emails out. The AI Assistant stays locked until you declare which surveys it may use. Public data you load as an ordinary survey follows the same rules as your own. More on this in what the assistant may see.
Which public sources are worth using, and what should you watch for?
In short: for workforce programs and grant makers, three federal sources cover most needs: wages, employer enforcement records and charity filings. Each is reliable for what it measures and misleading when stretched past it.
| Source | What it gives | How to bring it in | Watch out for |
|---|---|---|---|
| Your CRM, such as HubSpot | Employer partners and hiring history | Live query through MCP | Employer names spelled differently |
| BLS Occupational Employment and Wage Statistics | Wages by occupation, state and metropolitan area, with percentiles | Download yearly; load as a reference survey | A year old when published; all workers, not new hires; no county figures |
| Department of Labor enforcement data | Wage and hour cases and OSHA inspections by employer | Search before adding an employer partner; load the results | Name matching is loose; no record is not proof of good practice |
| ProPublica's IRS Form 990 search | Revenue, expenses, assets and pay of tax-exempt applicants | Look up each applicant; load the fields you use | Filings lag a year or two; small groups file a short form |
Confirm a charity's current status with the IRS's own Tax Exempt Organization Search. Record the download date and reference year of every loaded file, so the comparison can be traced to its source.
Prompt · paste into Claude, ChatGPT or your AI tool
I will give you two tables. Table 1: our starting wages, hourly, by training track, for people placed in a job within [PLACEMENT WINDOW] of exit, with the count of people per track. No names. Table 2: BLS Occupational Employment and Wage Statistics for [AREA], reference year [YEAR], with the SOC code, 25th percentile and median hourly wage.

1. Match each track to one SOC code. If a track fits no code or several, say so and skip it.
2. For each matched track, show our wage, the BLS 25th percentile and median, and the difference per hour.
3. List every difference in definition (who is counted, area, period, new hires vs all workers).
4. Do not estimate any missing value. Mark it "missing".
5. Write two plain sentences for a board, naming the area and the BLS year.
ASK ANY TOOL, INCLUDING OURS
Connect your CRM and program data to any assistant that supports MCP and ask: "Which employer partners hired our graduates last year, and how many were still in the same job at 12 months?" Then ask for the records behind each count. In Sopact Sense, answers trace to records you can open, and loaded public data sits beside your surveys under the same rules.
What can outside data not tell you?
In short: it gives context, not proof. Public data lags, uses its own geographies, and shows how two numbers relate, not why.
Wage estimates describe a year that has passed; your graduates started work this year. Metropolitan areas rarely match your service area. If graduates earn above the local 25th percentile, report it, but it does not show the training caused it: the people who enroll may differ from the typical local worker. Keep the comparison beside your own results, never in place of them.
Try it on your own reporting
- Write one question that needs data from outside your records. Decide whether you would ask it weekly (live query) or yearly (load once).
- Pick one dictionary metric with an outside match, such as starting wage by track, and write both definitions in one row.
- List every difference in who, area, period and unit. Mark each one "note it" or "stop".
- Name the fields you will send to an AI tool; confirm no names or contact details are among them.
- Run the prompt and read its list of differences before its sentences.
Check your reasoning
In the fictional workforce fund, the employer question is a live query, because its answer changes as placements come in. The wage benchmark is loaded once, from one BLS reference year. Partners A, B and D are compared track by track for their 100 people placed within 90 days. Partner C stays out until it splits wage by track and confirms its 90-day count. BLS covering all workers, not new hires, is a difference to note, not a reason to stop.
Questions teams ask
Is BLS wage data current enough for this year's report?
It is the most complete source for wages by occupation and area, but each release describes a period about a year before publication. Use it as context, name the reference year beside every figure, and repeat the comparison when the next release appears.
Can we compare with the county wage for the same job?
Not from the occupation wage survey, which publishes national, state and metropolitan or nonmetropolitan area figures, not county figures. BLS publishes county wages in another program, but by industry rather than by job. Choose the metropolitan area where most graduates work, name it, and note that it may be larger than your service area.
Does a live query through MCP copy our data to the AI provider?
The data stays in its own system, but the answers a query returns go to the AI tool you use, under your plan's terms. So decide which fields may leave each system before you connect it, and keep names and contact details out. Agree as a team which connectors are allowed, and review that list when staff or tools change.
Can outside data show that our program raised wages?
No. A benchmark shows how your graduates' wages compare with local wages for the same job, not what they would have earned without the program. To estimate that, you need wages before enrollment for the same people and a careful view of what would have happened anyway. The dollar value chapter walks through that step.