


Related solution
Membership & Networks
Connect stakeholder feedback with participation and program learning.
Explore the solution →


Live webinar: Wednesday, October 7, 2026 | 9:00 AM PT
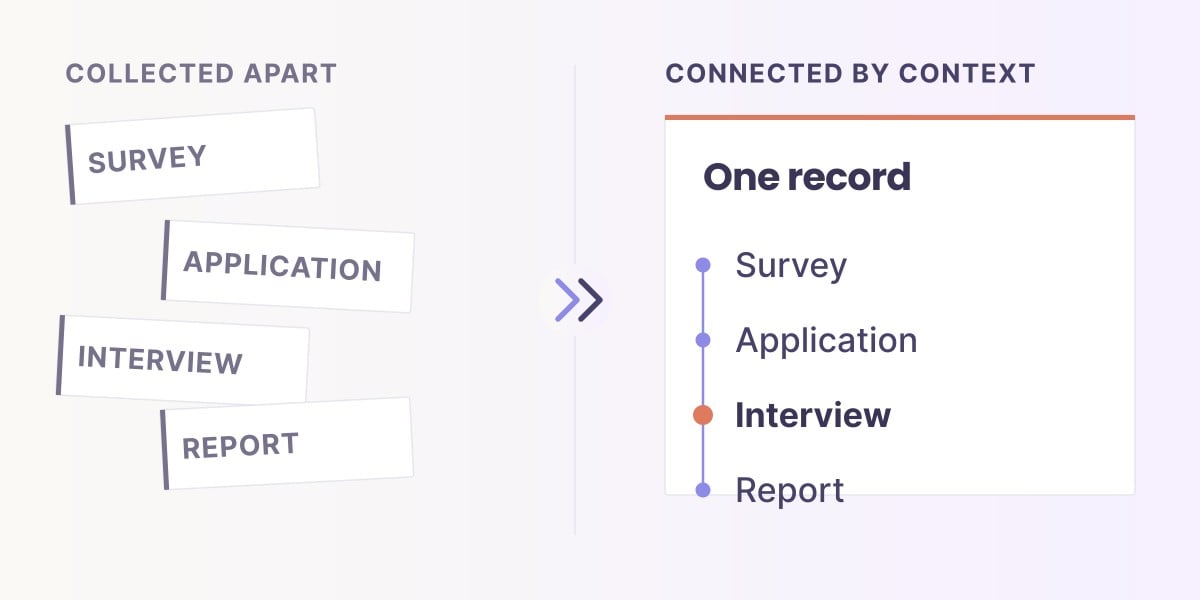
Building context across your data. In 30 minutes, see how to connect data and definitions across teams, with the right permissions and governance, so scattered data points become intelligence your teams and AI can actually use.
Save your spot (free)USE CASE / SOFTWARE GUIDE
Thematic analysis software helps researchers and program teams organize qualitative material, code relevant passages and develop an understanding of patterns across interviews, written feedback, notes and documents. Good software keeps interpretations connected to their sources, supports revision as understanding develops, and makes the findings useful to the people who need to act on them.
The challenge is more than reading a large volume of text. A theme can lose its meaning when the question, participant group or collection period is missing. Repeated feedback creates another problem: the team finishes one analysis just as the next set of responses arrives. A research study, a customer-feedback program and a training program therefore need different kinds of software support.
AI now assists coding, summaries and theme development across several platforms. The useful distinction is how that analysis fits the work: close interpretation of a research dataset, continuous customer listening, or understanding participant experience throughout a program. Sopact focuses on the third need, connecting incoming analysis with forms, files and earlier evidence so teams can use it in AI Assistance and continuing follow-up.
Read the pattern with the source and circumstances behind it.
Consider feedback alongside participation, assessments and earlier responses.
Keep new analysis available for questions and timely follow-up.
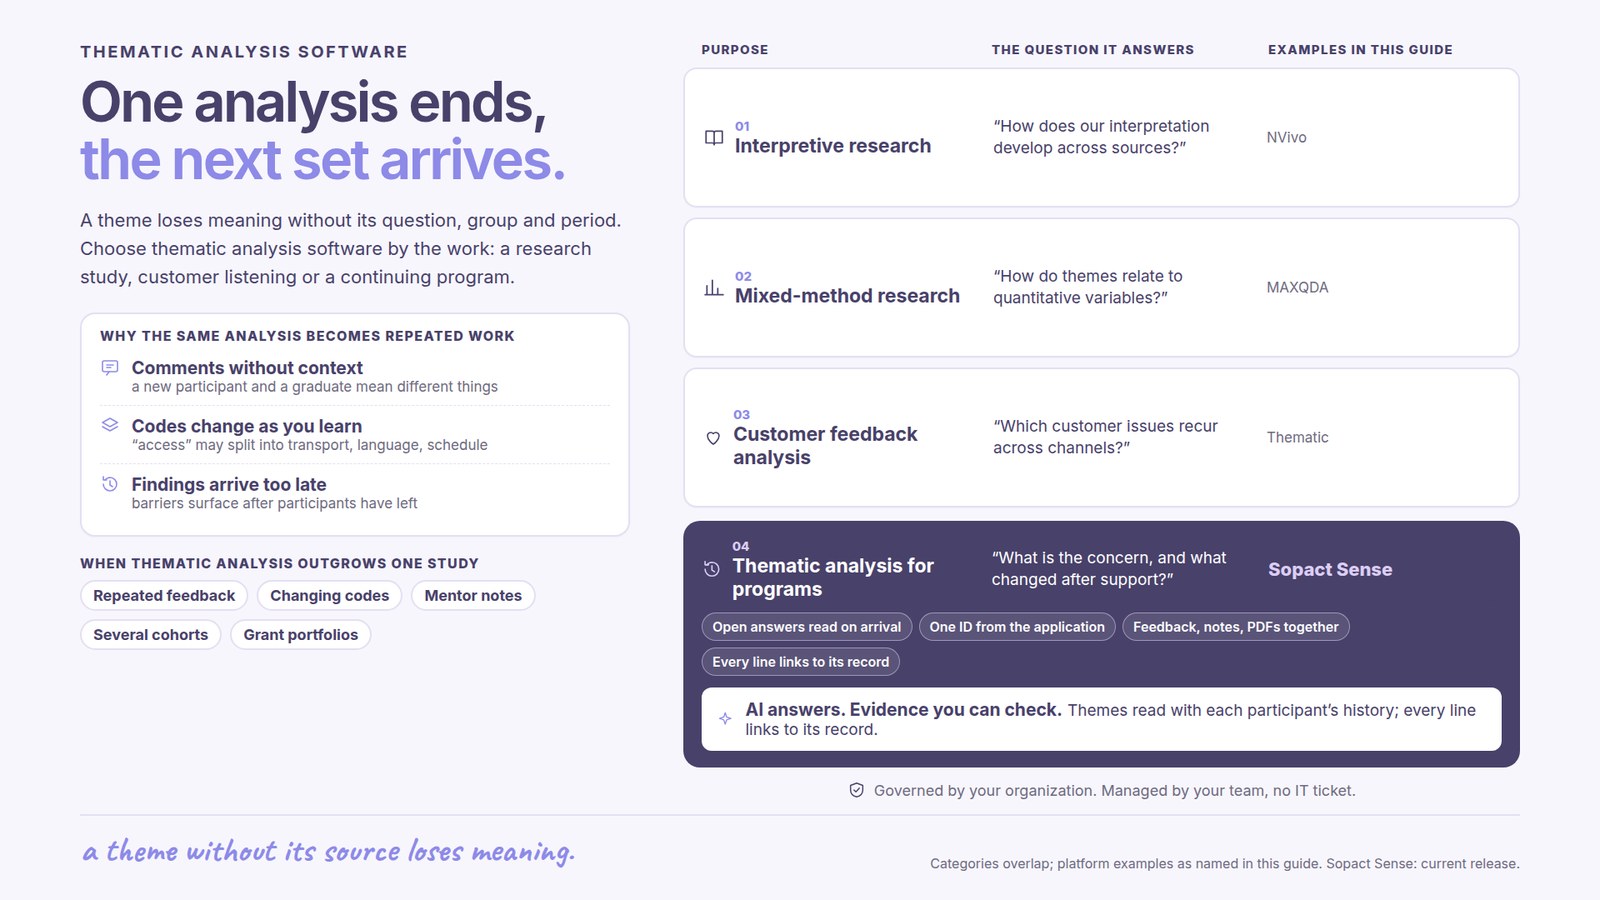
A comment about poor support means more when the team knows which program, stage and question it relates to. Combining text from several sources without that context can hide an important difference: a new participant describing onboarding is not necessarily reporting the same problem as a graduate seeking later support.
An initial category such as “access” may eventually need separate treatment for transport, language and scheduling. The buyer’s concern is whether the team can refine its understanding and retain a meaningful account of earlier findings. Faster initial coding is useful, but recurring analysis also needs manageable revision and review.
When feedback waits for a quarterly export and a separate analysis exercise, staff may learn about a barrier after the participants have left. Ongoing programs benefit when incoming evidence is available while there is still time to ask a follow-up question or change support. The relevant measure of value is the work between receiving a response and making an informed decision.
Braun and Clarke distinguish several approaches to thematic analysis, including reflexive, codebook and coding-reliability approaches. They do not make the same assumptions about how themes are developed or how quality should be assessed.
For an interpretive research study, the researcher needs room to read closely, write analytic memos, revise codes and develop themes. For recurring operational feedback, agreed categories can help a team compare concerns across periods while leaving room for new findings. A software-generated topic list does not establish that either kind of analysis is complete.
This distinction affects the buying decision. Research teams may prioritize the depth of the coding workspace and methodological flexibility. Customer teams may prioritize incoming feedback channels and issue trends. Program leaders may need feedback connected to participant history, assessments and later progress. These purposes can overlap, but they should not be treated as identical purchases.
MAXQDA supports coding, memos, theme development and examination of relationships within a research project. Its AI Assist also supports coding and summaries, while mixed-method functions connect qualitative analysis with quantitative variables.
It is a relevant shortlist choice when the researcher’s analytical workspace is central to the purchase. The practical question for a recurring program is how new material, participant attributes and reporting responsibilities will be maintained across cycles.
NVivo belongs in a research-software shortlist. Its direction is also changing: Lumivero’s September 2026 NVivo AI Cloud announcement describes source-linked AI suggestions, continuing codebook development and researcher approval. As of October 4, the vendor lists individual availability from October 6 and a later waitlist for teams and institutions.
That announced edition should be distinguished from the version a buyer can currently obtain. It also shows why “traditional software versus AI” is an inadequate comparison. Research method, analyst control, availability and the ongoing collection workflow are more useful criteria.
Thematic focuses on feedback across sources such as surveys, reviews and conversations. Its documented capabilities include automatic theme discovery, a human theme editor and links from themes to underlying comments. Teams can also examine new data for additional themes.
This is relevant when the central responsibility is understanding recurring customer issues across channels. The buyer should consider the feedback sources and the actions the CX team needs to take.
Sopact is relevant when qualitative feedback needs to explain participant or partner progress. An application describes an initial goal, assessments describe a starting point, and later comments and notes explain the experience of the program. Keeping that information together makes the analysis useful for delivery as well as reporting.
The buying reason is continuity: staff can ask about a developing concern with the related evidence already connected. This is especially useful for training, accelerators, grants and membership programs where understanding evolves across several interactions.
A training team might see improving assessment scores alongside comments about difficulty applying the skill at work. The scores and the comments answer different questions. Considering them together can help the team distinguish learning from the conditions needed to use it, then decide whether mentoring or employer support would help.
Sopact’s documented approach connects forms and analyzes written responses and PDFs while retaining the relevant record relationships. In a configured workflow, analysis becomes available as data arrives and can be used through AI Assistance. Staff can examine the incoming feedback against earlier evidence without beginning each question with another export and coding exercise.
For an accelerator, this can connect application goals, onboarding, mentor notes and later progress. For a grant portfolio, it can connect the partner’s original plan with narrative reports and community feedback.
This is the practical AI-native distinction for Sopact: analysis is part of collection and continuing program knowledge. It extends beyond generating a summary of a single document. People still interpret the findings, investigate conflicting accounts and decide what to do.
A theme should lead the reader back to the material that supports it. The question, program and collection period can change the meaning of the same words. A source link helps a reviewer examine an interpretation; it does not make every interpretation correct.
High frequency does not automatically mean high importance. A relatively uncommon concern may need attention because of its consequences. Positive and negative comments about the same topic may also require different responses. Useful analysis preserves that distinction instead of presenting one undifferentiated count.
In a fictional example, 100 people submit a survey, 80 provide a usable comment and 24 of those comments mention scheduling. That is 30% of commenters. It is not evidence that 30% of everyone invited experienced a scheduling problem. The meaning also depends on whether the comments describe a barrier or praise the flexibility offered.
A program team needs these distinctions to decide where to act and how confidently to report a result. The software should make the relevant evidence understandable without requiring the reader to reconstruct the analysis from separate files.
Sopact’s published ASME account describes stakeholder feedback that had been collected for years but used mainly as impact stories. The work brought qualitative and quantitative material into a shared view and examined open-ended scholarship responses, revealing concerns such as avoiding debt and completing a degree.
The useful lesson is that existing feedback can help explain what participants value when it is analyzed alongside the rest of the program information. This is a historical Impact Cloud customer account, rather than a measured benchmark for the speed or accuracy of the current AI workflow.
Sopact’s typical setup estimate is two days to two weeks for an agreed workflow. The scope should account for the material already collected, the questions the team needs to answer and the relevant relationships across sources. This is an operating estimate, not a guarantee that every historical dataset or integration fits the same timetable.
Once the workflow is configured, analysis is available as new data arrives. Time to analysis and time to a reviewed conclusion are different: a team may still need to read ambiguous responses, contact participants or consider a change with program colleagues. The benefit is reducing preparation so that attention goes to interpretation and action.
Self-governance means the team retains control of its questions and routine work, with personalization and continuing Sopact support as the program changes. For a specialist research project, methodological expertise remains important regardless of the software. For recurring program feedback, ownership also includes keeping the questions, definitions and reporting responsibilities useful from one cycle to the next.
Choose a research workspace when the primary task is developing and documenting an interpretation within a study. Choose a customer-feedback platform when the central job is monitoring experiences across customer channels. Consider Sopact when the findings need to remain connected to participant or partner history and inform continuing program decisions.
For the wider research category, see qualitative data analysis software. If the main buying question concerns survey reporting, see survey analysis software. Keeping those purposes clear is more useful than selecting whichever tool produces the fastest first summary.
Thematic analysis software supports organizing qualitative material, coding passages and developing patterns of meaning across sources. Good software helps analysts retain context, inspect supporting material and revise interpretations.
The choice depends on the work. MAXQDA and NVivo are relevant to qualitative research; Thematic focuses on recurring customer feedback; Sopact connects analysis with continuing participant and program evidence. The method, sources and decisions should guide the shortlist.
AI can assist coding, summaries and preparation. People remain responsible for choosing an appropriate method, understanding context and interpreting findings. A topic list or source citation alone does not establish a sound conclusion.
No. Reflexive, codebook and coding-reliability approaches differ. A maintained category structure may serve recurring operational reporting, while an interpretive study may need a more evolving approach.
Sopact connects incoming analysis with forms, files and relevant program history. The configured analysis is available through AI Assistance for continuing questions and follow-up, rather than ending with a summary of one document.
Continue with a purpose
Related solution
Connect stakeholder feedback with participation and program learning.
Explore the solution →Continue learning
Plan connected collection and useful analysis across a network.
Start learning →
Customer story
Qualitative stakeholder feedback became part of a shared analytical view.
Read the story →See how Sopact connects qualitative analysis with participant history and the questions your team needs to answer next.
See it with your workflow →