What is program evaluation?
Program evaluation is the systematic collection and analysis of evidence to assess a program’s design, delivery, outcomes or value and inform a decision about what to do next. It is broader than counting activities, and it does not always need to estimate causal impact.
Start with who will use the finding and what they will do with it. A team improving delivery next quarter needs different evidence from a funder deciding whether to renew a grant, and both differ from a board asking whether the program caused the change.
Often the first obstacle is fragmented evidence: the intake survey, attendance sheet, staff notes and follow-up answers describe the same people but live in separate files. The explainer above shows how connected participant records support evaluation across that journey. AI can help organize and interpret the evidence; the evaluation question, research design and human judgment still determine what the findings mean.
The short version
- Choose the type of evaluation by the question and the decision: process for delivery, outcome for what changed, impact for what the program caused.
- Write the questions from your theory of change, level by level, and agree how each outcome is defined before any data is collected.
- Keep surveys, attendance and follow-up linked to the same participant; report who is missing from each comparison.
- Use numbers to locate a pattern and participant feedback to investigate it. Review AI interpretations against their sources.
- State what the design supports: observed change is not proof that the program caused it. Assign an action, an owner and a review date.
What are the main types of program evaluation?
Five types cover most needs: formative, process, outcome, impact and economic evaluation, and each answers a different question and supports a different kind of claim. The last column is the one teams most often skip.
| Type | Typical question | Possible evidence | What it can claim |
|---|---|---|---|
| Formative | How should the program be designed or improved? | Needs assessment, interviews, pilot findings | What to change before scaling |
| Process | Was it delivered as intended, and to whom? | Delivery records, observation, participant accounts | How the program ran |
| Outcome | What changed for participants? | Defined measures per person at set time points | Change among people reached |
| Impact | What change is due to the program? | A design with a comparison or counterfactual | Contribution or attribution, within limits |
| Economic | How do costs relate to results or alternatives? | Defined costs plus outcome evidence | Value, under stated assumptions |
The categories overlap, and one evaluation often combines two. Name the actual question and design rather than relying on a label to explain what the evaluation can conclude.
Which program evaluation methods should you use?
Choose methods by the question, the evidence available and the claim you need to make. An evaluation type names the purpose; a method describes how you collect or analyze evidence. A mixed-methods evaluation combines quantitative measures with qualitative accounts to investigate both the pattern and its possible explanations.
| Method | Useful for | Check before interpreting |
|---|---|---|
| Surveys and assessments | Knowledge, skills, experience and reported outcomes | Use comparable wording and scoring; distinguish self-report from demonstrated ability. |
| Interviews and open-ended feedback | How participants experienced the program and why barriers persist | Keep quotations in context; a few interviews do not establish prevalence. |
| Attendance and service records | Reach, participation, completion and delivery | Count unique people and define what counts as participation. |
| Pre/post and longitudinal analysis | Change in the same people and whether it lasts | Match participant IDs, keep measures consistent and report missing follow-up. |
| Comparison designs | Whether change may be attributable to the program | Assess selection bias and alternative explanations; a comparison alone is not enough. |
For repeated measures, use the pre and post survey guide. For choosing between following the same participants and comparing groups at one point, see longitudinal study design.
How do you use a logic model for program evaluation?
A logic model connects inputs, activities, outputs and outcomes. A theory of change also explains why those connections should hold and the assumptions behind them. Use both to turn program planning into evaluation questions: what should happen, for whom, by when, and what evidence would challenge the explanation?
Read the theory of change level by level: the delivery levels give process questions, the outcome levels give outcome questions, and the arrows between them give the why and how-much questions an impact evaluation takes on. The model tells you which questions matter; the decision tells you which to answer first.
Take a fictional job-training partner of a regional workforce fund, the running example in the course Measurement and reporting. Its pathway: training and mentoring → certification → placement within 90 days → retained at 12 months → living-wage jobs. Its reporting agreement already names the outcomes, which spares the evaluation a definitional argument later.
Process questions sit on the first boxes. Did every trainee get a mentor? Did people who enrolled finish the track, and who dropped out, at which point and why?
Outcome questions sit on the outcome boxes. How many graduates were placed in a job within 90 days of exit, and how many were in the same job at 12 months? What was the hourly starting wage on each track, and who is missing from each count?
Impact and economic questions sit on the arrows: would these graduates have found similar jobs anyway? Do employers hire because of the certification? What does each placement cost, set against the wage it leads to?
If you do not have a model yet, the course chapter One change model, four formats builds one level by level, with the assumption under each arrow. The assumption you trust least is usually your best first evaluation question.
The video below walks a skills program from activities to impact in about seven minutes. As you watch, sort each result it names into process or outcome; that sorting is the first step of an evaluation plan.
Watch the theory of change walkthrough
Program evaluation example: a workforce training program
Suppose a fictional training team wants to understand whether participants use new skills at work 90 days after exit. Its evaluation connects delivery, learning and follow-up rather than treating a satisfaction score as the outcome.
- Intake · establish the baselineIssue one participant ID. Record the initial skills assessment, goals and cohort.
- During delivery · investigate participationLink attendance, support received and feedback to that ID. Note which barriers the team can address.
- Exit · compare like with likeRepeat the assessment with the same scoring. Separate skill change from satisfaction with the course.
- Follow-up · check use over timeAsk whether the skill is used at work, retain the source response and record who did not answer.
Illustrative workflow, not a reported customer result. The same ID connects every stage; each measure keeps its date and definition.
Keep the denominator visible. If 120 people enrolled but only 80 have both baseline and exit assessments, describe change among those 80 and account for the other 40. Do not present the matched group as all participants. Check whether missingness is concentrated in a site, cohort or attendance pattern.
The next question might be why one cohort reports less skill use despite similar exit scores. Read their feedback alongside participation records, discuss the finding with participants and test a specific delivery change. This supports learning; it does not establish how much change the training caused.
SOPACT VIDEO LIBRARY
See how Sopact supports program evaluation
Connect participation, assessments and feedback to review your programs—with impact measurement built in.
Explore the video library →
Illustrative AI-generated imagery
What does an outcome evaluation need before it starts?
It needs agreed definitions and records that follow each person, because an outcome evaluation can only compare results counted the same way, for the same people, over the same window. Outputs can be counted at the end; outcomes have to be measured per person over time.
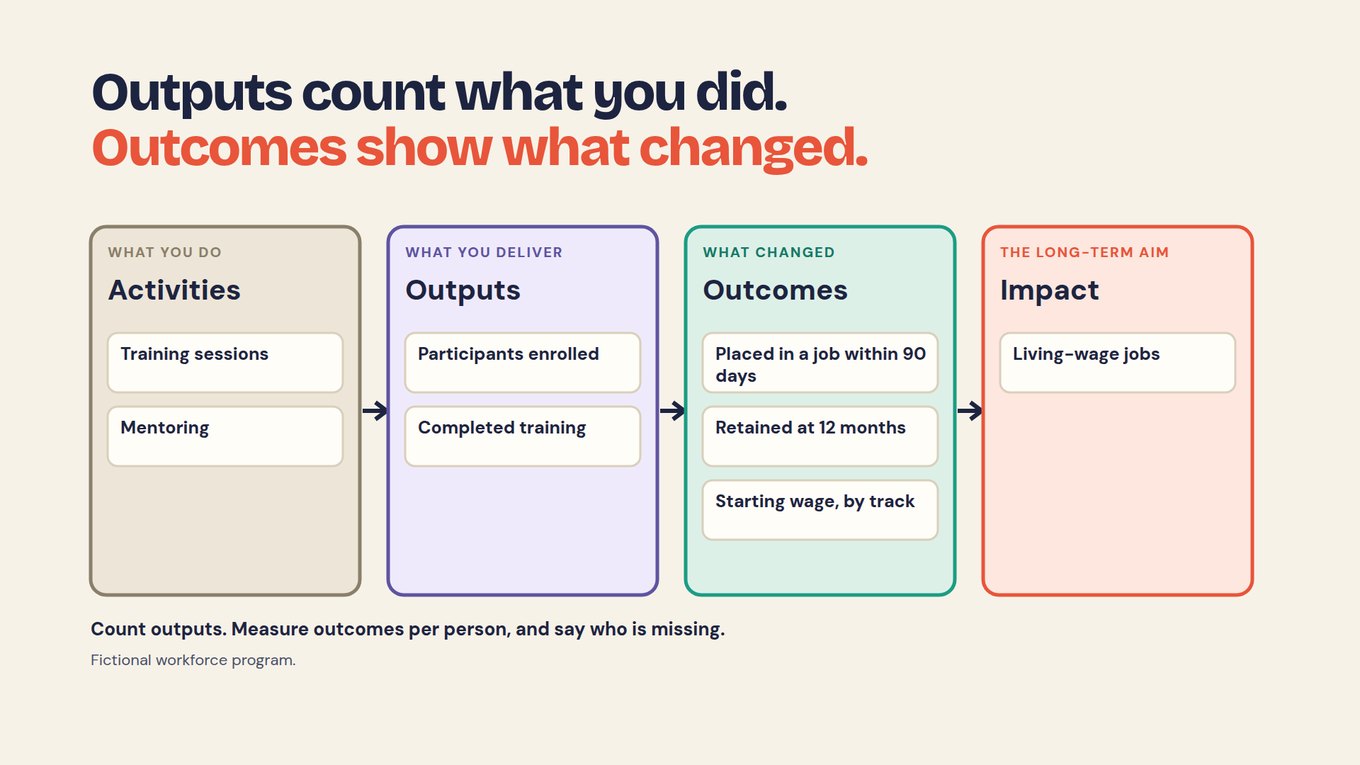
Definitions decide what an evaluation can say. When the workforce fund added up placements within 90 days, Partners A, B and D reported 42, 31 and 27, a total of 100. Partner C reported 55 placed within six months, a different window, so the fund held that number rather than add it.
An evaluator would face the same choice. Mixing windows makes the total larger and the finding wrong, so the definitions have to be settled in the agreement, before collection. The chapter Roll up and benchmark portfolio results shows the full roll-up.
Per-person outcomes also need the same person at each point: intake, exit, the placement survey and the 12-month follow-up. In Sopact Sense, each participant keeps one ID from the first form and later surveys add to the same record, so the evaluation starts from linked data instead of matching spreadsheets by name.
What should a program evaluation survey ask?
A program evaluation survey should ask only what participants can reliably report and what your evaluation needs to know. Combine repeated measures with a few open questions; do not use satisfaction as a substitute for learning or longer-term outcomes.
| When | Example question | Use |
|---|---|---|
| Baseline and exit | How confident are you completing [specific task] without help? Use the same 1–5 scale each time. | Compare reported confidence; pair with a demonstration of the skill. |
| During the program | What made it difficult to attend or take part this week? | Identify barriers the team can investigate while delivery continues. |
| Exit | Which activity helped you most, and what would you change? | Understand experience and possible improvements. |
| 90-day follow-up | During the past 30 days, how often have you used [skill] at work? | Measure reported use over a defined period. |
| Follow-up | What helped or prevented you from using what you learned? | Investigate the conditions behind the outcome. |
These are illustrative questions, not a validated scale. Pilot them, carry the participant ID into each wave and keep definitions stable. Use the pre/post question examples and matching guidance when building your survey.
How do you know whether the program caused the change?
You need a comparison that shows what would likely have happened without the program; a before-and-after change on its own cannot separate the program from everything else that moved. A stronger local job market, for instance, can lift placements whatever the training did.
Comparison groups formed before the program starts give the strongest answer, and usually need an evaluator. A program team can still do honest, lighter comparisons: earlier cohorts measured the same way, or outside data on the same definition, such as a county median wage for the same job. The chapter Compare your results with outside data covers when that is fair.
Choose the claim before the design: “graduates were placed at this rate” needs good outcome data. “The program contributed to placements” needs outcome data plus evidence on the arrows. “The program caused this many placements” needs a counterfactual design, planned before collection.
The video below compares the two designs most teams choose between, following the same people over time or comparing groups at one point, and asks which one funders accept as evidence the program caused the change.
Watch the research-design comparison
How do you plan a program evaluation? Six steps and a template
The 2024 CDC framework organizes evaluation around assessing context, describing the program, focusing the questions and design, gathering credible evidence, generating supported conclusions and acting on findings, with collaboration, equity and use running through all of it. Read the current framework.
- Understand the setting. Name the decision, intended users, resources and constraints.
- Describe what the program does. Map delivery and expected outcomes in a logic model.
- Choose the questions and design. Decide which uncertainties matter and what evidence can answer them.
- Collect credible evidence. Set definitions, timing, participant identifiers and quality checks.
- Develop supported findings. Compare results, examine missing data and test alternative explanations.
- Use what you learn. Agree a change, assign responsibility and set a date to review it.
Treat it as a planning structure, not a rigid sequence; something found during collection may send you back to the design. The plan itself can be short. Here is the template, filled in for the fictional workforce partner.
| Plan element | Decision to record | Workforce example |
|---|---|---|
| Purpose | Who uses the findings, for what decision, when | Fund and partner, grant renewal, next year |
| Program | What work, population and period | Training and mentoring, one year of cohorts |
| Questions | Which uncertainties matter most | Placement within 90 days; retention at 12 months |
| Design | What evidence and comparison can answer them | Outcome evaluation, earlier cohorts as context |
| Collection | Sources, timing, responsibilities | Placement survey quarterly; follow-up at 12 months |
| Analysis | Calculations, coding, quality checks | Unique people, by track, missing named |
| Use | How findings are discussed and acted on | Monthly learning review; one change, owner and review date agreed |
Add the budget, access needs and the main limits. A question that needs evidence you cannot get should be narrowed, not quietly answered with what you have.
PROMPT · PASTE INTO CLAUDE, CHATGPT OR YOUR AI TOOL
Below is our theory of change and the decision our evaluation must inform. Draft evaluation questions and a short plan.

Rules:
1. Sort questions into process, outcome and impact, and say which level or arrow of our model each one comes from.
2. For each outcome question, state the definition it depends on (unit, time window, who is counted), using only definitions in our materials.
3. For each question, say what design could answer it and what claim that design supports. Do not suggest a causal claim without a comparison.
4. Do not invent numbers, baselines, targets or findings. Where something we need is missing, write "not in our data".
5. End with the one question you would answer first for our decision, and why.

Our decision:
[PASTE]

Our theory of change:
[PASTE]

Our reporting agreement or indicator list:
[PASTE, OR WRITE "NONE"]
Where does evaluation fit in monitoring, evaluation and learning?
Evaluation belongs in an ongoing learning cycle: agree what to monitor, collect evidence during delivery, investigate what changed and for whom, then decide what to adjust. Monitoring feeds the evaluation its data, and learning feeds the findings back into the program.
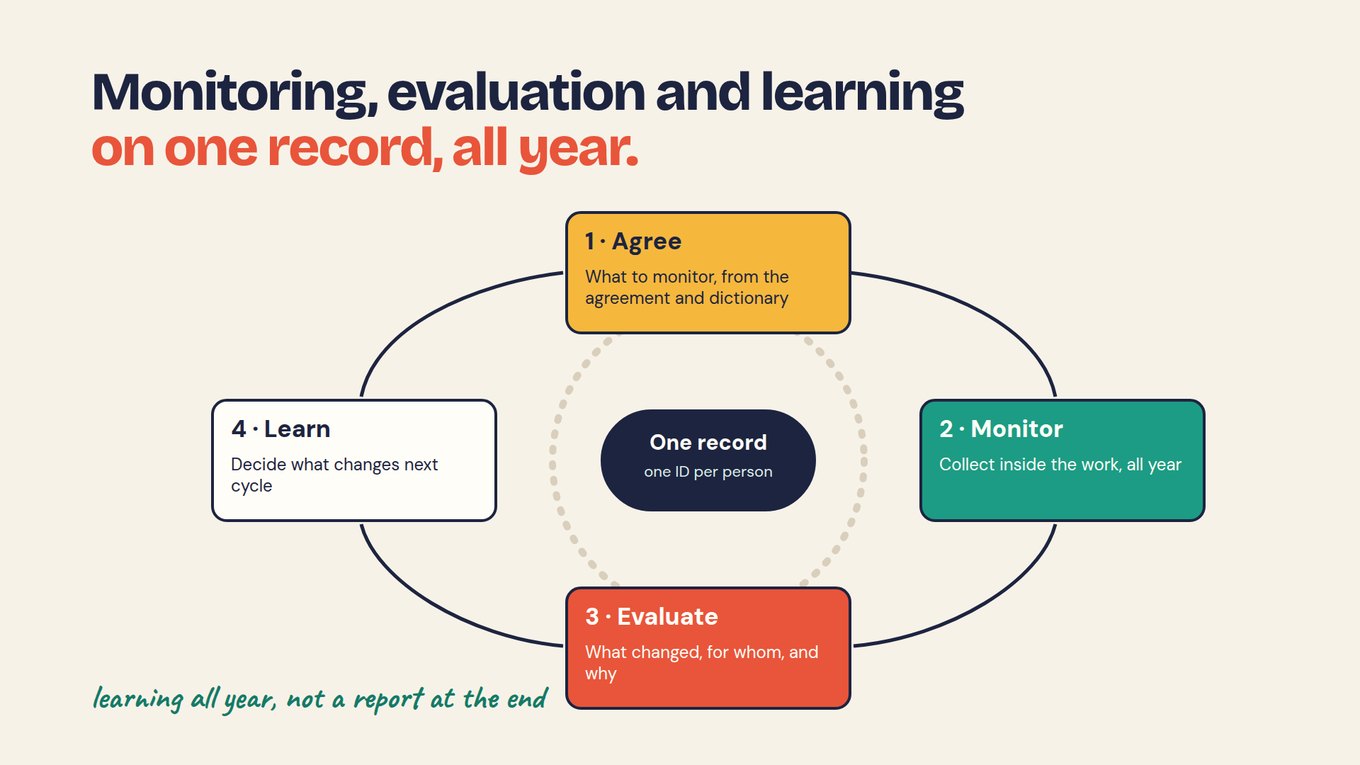
Here is how a finding travels. Suppose the partner’s completion is high but placements within 90 days lag on one track. A process look finds that track has few employer contacts, so the fix is outreach to employers, not more training hours.
That finding guides delivery; it does not estimate how many placements the program caused. Write each conclusion with its evidence, interpretation and limit, then agree the action, an owner and a review date. For the monitoring half of the loop, see using a theory of change in M&E.
How can AI support program evaluation and continuous learning?
AI can help organize qualitative feedback, locate patterns and draft questions for further investigation when the underlying records are connected and the findings remain reviewable. It does not repair an unsuitable evaluation design, reveal outcomes for nonrespondents or establish causality by itself.
In the Sopact Sense workflow introduced in the video, surveys, attendance and follow-up remain related to the participant. A program team can investigate a change in an outcome alongside what those participants said and which activities they attended. Check the underlying records and quotations before adopting an AI-generated explanation.
- Collect in context. Keep the participant, program, cohort, date and measurement definition with each source.
- Investigate the pattern. Compare relevant groups, review feedback themes and look for contrary evidence and missing records.
- Decide and revisit. Record the interpretation, its limits, the agreed action and what will be checked at the next review.
A dashboard can show where an indicator changed. Continuous learning adds the follow-up question, source review and decision. See the collect, analyze and improve learning cycle for a practical starting point.
What should program teams look for in evaluation tools?
A survey tool is useful for collecting responses. A CRM can manage relationships and activities, and may be configured for evaluation. Program data management connects evidence across the delivery cycle. Judge each approach on a real workflow, including the work needed after the first report.
- Implementation effort
- Test one program and one evaluation question. AI-assisted setup is valuable when it reduces configuration work while keeping definitions and relationships reviewable; ask what still needs specialist help.
- Program-team ownership
- Check whether staff can adjust collection, investigate findings and manage routine changes themselves. Include IT where integrations, permissions or governance require it.
- Connected participant evidence
- Verify that repeated surveys, attendance, notes and follow-up stay related to the same person. Ask how duplicates, missing matches and changed definitions are handled.
- Total cost of ownership
- Include migration, setup, integrations, consulting, training, analysis and ongoing maintenance alongside the subscription. Compare the effort across multiple reporting cycles.
- Learning and action
- Test whether a team can move from a result to its evidence, an explanation worth checking and a documented action. A polished dashboard is one part of that workflow.
The Training & Programs solution shows how Sopact applies this approach from enrollment through follow-up. Use your own definitions and a small representative dataset to assess fit.
What can a program evaluation not tell you?
An evaluation can only be as strong as its design and its data, and most program evaluations describe change without proving cause. A satisfaction score, however high, cannot stand in for a skills assessment or a job.
Non-response is the quiet threat: the graduates who stop answering by 12 months may be the ones who lost their jobs. Document who is missing and compare respondents with non-respondents on what you already hold. A few interviews explain mechanisms well but cannot establish a population rate.
AI can help organize records and draft findings, but check every line against the records it cites, and let an accountable person decide what the results mean. Involve the people affected in interpreting findings, not only in supplying data.
Start with one evaluation question this cycle
Pick the one decision coming up soonest and evaluate only what it needs.
- Write the decision and who will make it, with a date.
- Find the level or arrow of your theory of change that decision depends on.
- Write one evaluation question and name its type: process, outcome or impact.
- Check the definition behind it against your reporting agreement, and fix any mismatch before collecting.
- List the records you already hold, and collect only what is missing.
- Write the finding with its evidence, its limit and one agreed action.
After the first cycle you have one answered question, a definition both sides trust, and a clear sense of which question, and which design, comes next.
Frequently asked questions
Is monitoring the same as evaluation?
No, though they feed each other. Monitoring tracks a few agreed indicators on a fixed schedule while the program runs, such as placements each quarter. Evaluation asks a specific question at a planned point, such as why placements lag on one track, and supports a judgment or decision. Good monitoring data makes an evaluation lighter to run, because many of the records it needs already exist.
What is the difference between outcome and impact evaluation?
An outcome evaluation measures what changed for the people a program reached, such as how many were placed in a job within 90 days. An impact evaluation asks how much of that change the program caused, which needs a comparison showing what would likely have happened without it. Many programs need the first every year and the second only occasionally.
Does every evaluation need a control group?
No. The design follows the question. Process and outcome evaluations do not need one. A control or comparison group matters when you want to estimate what the program caused, and even then earlier cohorts or outside data on the same definition can offer a lighter, clearly labelled comparison when a full design is not possible.
When should program evaluation start?
Plan it when the program is designed, not when the report is due. Definitions, baselines and follow-up points must be in place before collection, or the evaluation will depend on records that were never kept. Some questions can be answered afterward from existing records, but say plainly which limits that creates, especially for anything about cause.
Who should conduct a program evaluation?
Choose people with the skills and the independence the purpose needs. Program teams can run process and outcome evaluations well, especially with clean per-person records. Impact evaluations and evaluations meant to inform high-stakes funding decisions often benefit from an external evaluator. Internal and external roles can combine, with staff supplying data and context and the evaluator owning the design.
Can AI replace an evaluator?
AI can assist with organizing evidence, reviewing text and drafting analysis. People remain responsible for the evaluation questions, design, interpretation and decisions. Causal or high-stakes evaluations may require specialist expertise and independence.
Is programme evaluation different from program evaluation?
No. Programme evaluation is the spelling commonly used in British English; program evaluation is common in American English. Both refer to systematic inquiry into a program’s delivery, results or value.
An evaluation should inform the next decision as well as describe results. The impact measurement guide connects evaluation evidence with continuing program, stakeholder, partner and portfolio management.