What is outcome evaluation?
Outcome evaluation checks whether the changes a program intended for people actually happened, for whom and by how much, using outcomes defined before collection and measured on the same people over time. It looks at results such as skills used, jobs kept or services reached, not at activities delivered.
An outcome evaluation can ask whether a target was reached, how a group changed or how results differ between groups. It does not, by itself, show that the program caused the change. The CDC’s 2024 evaluation framework separates reaching outcomes from causal attribution, and that line runs through this guide.
THE SHORT VERSION
- Define each outcome with who counts, a time window and a missing-value rule before anyone collects it, such as placed in a job within 90 days of exit.
- Measure change per person on one ID across waves, and report the people you could not reach as unknown, never as a success or a failure.
- Outcome evaluation shows what changed and for whom; saying the program caused it needs a comparison design.
How is an outcome different from an output?
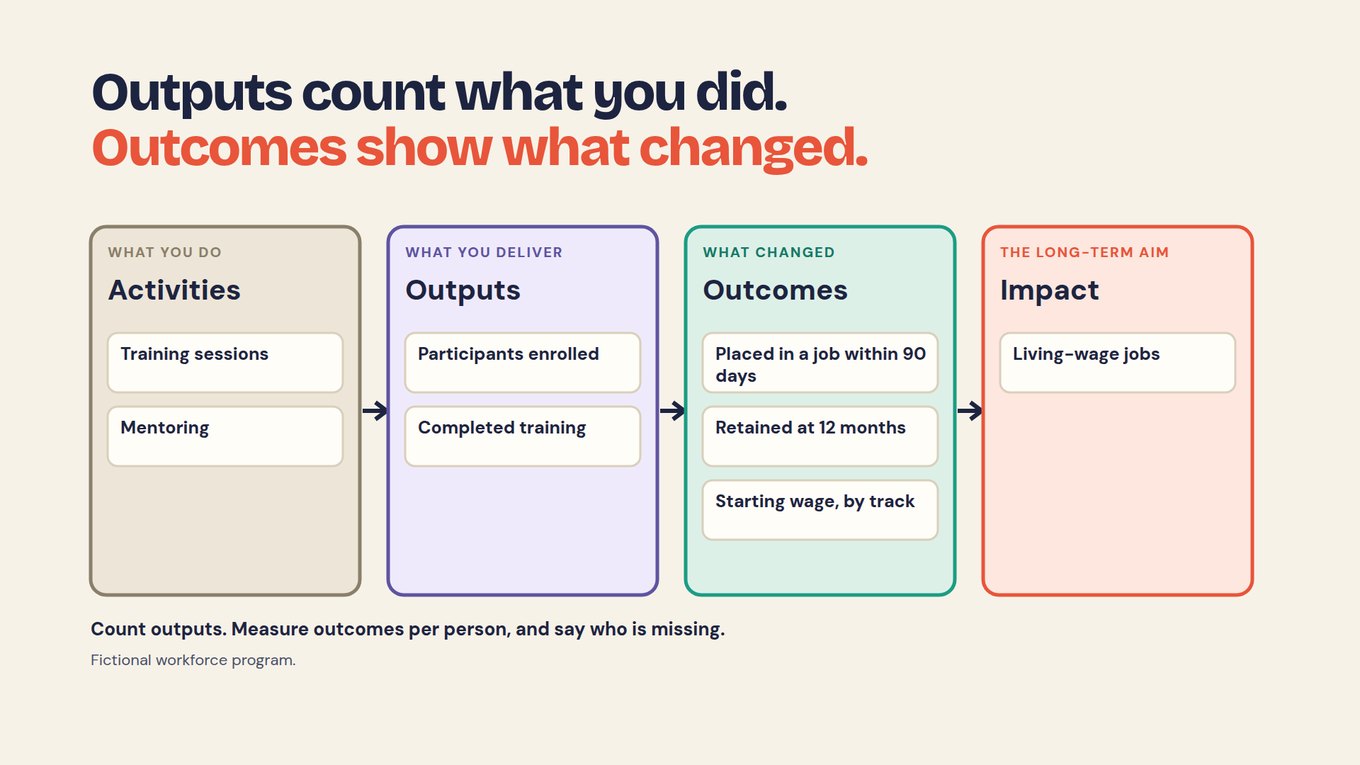
An output counts what the program delivered; an outcome is a change in people’s situation that the program intended, measured person by person. Evaluating outputs tells you the program ran. Evaluating outcomes tells you whether it mattered to the people in it.
In the fictional workforce program used across Sopact’s course, training sessions and mentoring are activities. Participants enrolled and completed training are outputs. Placed in a job within 90 days, retained at 12 months and starting wage by track are outcomes, and living-wage jobs are the long-term aim.
Two neighboring kinds of evaluation sit on either side. A process evaluation asks whether the program was delivered as intended; see program evaluation. An impact evaluation asks how much change the program caused, against a comparison; see impact evaluation.
How do you define an outcome so it can be evaluated?
Write each outcome as a dictionary entry: who counts, what qualifies, within what window, from which source, and what happens when an answer is missing. “Improve employment” is an aim; “completers in paid work within 90 days of exit” is something two people can count and get the same answer.
ONE OUTCOME, FULLY DEFINED · FICTIONAL EXAMPLE
Outcome: Placed in a job
Who counts: a trainee who completed the program and started paid work within 90 days of exit
When and where from: placement follow-up at 90 days, linked to the person’s enrollment record
Unit: yes or no per person, with completers as the denominator
Split by: training track, gender, age
If no answer: unknown, never “not placed”; report the unknown count
The second outcome follows the same pattern with a longer window: retained means the same job at 12 months, reported annually. Decide before the numbers arrive how to count a graduate who moved to a better job, because “same job” excludes them.
Test each entry on awkward records: someone who enrolled twice, a follow-up that came back late, a person who started work on day 95. The chapter A shared data dictionary gives the full entry, with a template and a prompt to draft it.
Which outcome evaluation design fits your question?
Choose the design by the question: attainment needs only a follow-up measure, change needs the same people measured twice, and persistence needs repeated follow-ups on one record. Each design answers one kind of question well and leaves others open.
Scroll horizontally to see all columns →
| Design | What it can show | Main limit |
|---|---|---|
| Post-program assessment | Whether a defined result was reached | No baseline, so no change from the start |
| Matched pre and post | Change among the same people | Does not remove dropout bias or show cause |
| Repeated cross-section | Patterns in a population over time | Shifts in who answers can drive the result |
| Longitudinal follow-up | Whether outcomes last across several points | Missing waves need explicit handling |
| Qualitative or mixed methods | Experience, context and unexpected effects | Needs a sampling plan; not proof of cause |
A named design is not enough on its own. Write down who is included, the observation period, what is compared and how missing answers are treated. If the funder needs a causal claim, plan a comparison design with an evaluator from the start.
How do you measure change per person over time?
Give each person one ID at the first form and add every later wave to that record, so change is calculated per person instead of by comparing two group averages. Two averages from different groups mix a change in people with a change in who answered.
If the people who answer a follow-up started out ahead of those who did not, the follow-up average rises even when nobody changed. Matching on ID removes that trap for the people you reached, and shows plainly who you did not reach. The pre and post surveys guide covers the matching in detail.
Girls Inc. of Metropolitan Dallas runs a coding program with pre, mid and post surveys and follow-ups at six months and one year, on a reporting cycle tied to a July 1 fiscal year. Its board asked hard questions about data privacy and AI before approving the approach, which is the right order.
In Sopact Sense, a persistent unique ID from the first form carries each person through every later wave on one record. Field selection lets you choose which fields are sent to AI, so names and emails stay out of any analysis.
The video below contrasts snapshots, a survey in January and a report in December with nothing linking them, with a pre and post survey on one record per person. Watch for what becomes possible once each answer carries the same ID.
How should you report people you could not reach?
Report them as unknown, with their count beside every result, because people who stop answering may differ from those who stay. Counting them as failures understates the program; dropping them silently flatters it.
Separate people not yet due for follow-up from those who declined, could not be reached or left. Record the planned denominator before you look at the result, then compare responders and non-responders on what you already hold, such as track or attendance. Advanced adjustments for missing data need justified assumptions and specialist help; they do not restore the missing answers.
For the fictional fund, a placement result reads as a set of lines, not one number.
| Report line | Workforce fund, placed in a job |
|---|---|
| Definition | Completers in paid work within 90 days of exit |
| Placed | 100 across Partners A, B and D (42, 31, 27) |
| Denominator | Completers at each partner, stated beside the count |
| Unknown | Completers with no follow-up answer, counted separately |
| Held | Partner C’s 55, counted on a six-month window, until it confirms 90 days |
When should you measure each outcome?
Measure when the change could have happened: placement 90 days after exit and retention at 12 months, not at the last training session. A satisfaction survey at the last session is useful feedback, but it cannot tell you whether someone kept a job.
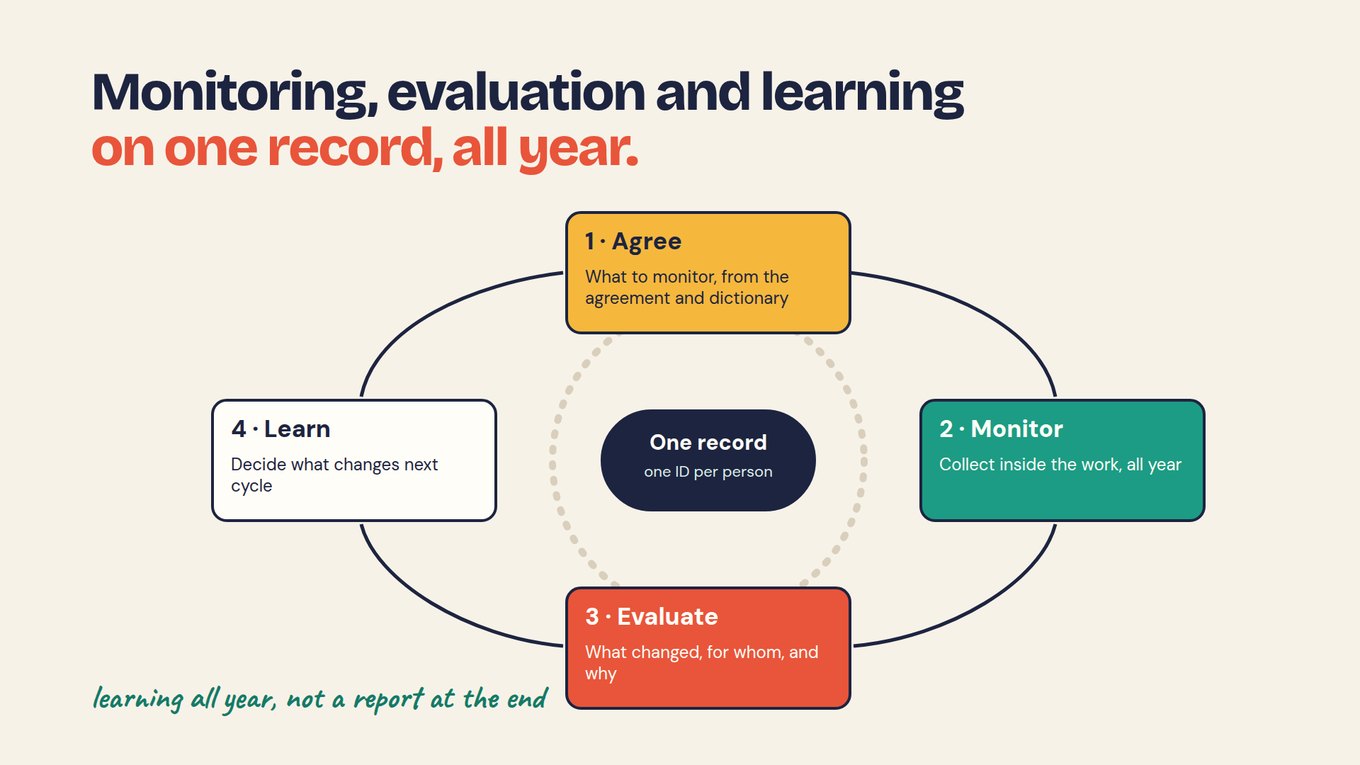
An endline measure is not wrong in itself; some outcomes can only be judged late. Add a mid-point when it can inform an earlier decision, and avoid repeated questions that add burden without adding meaning. Across the year, the pattern is a loop: agree what to monitor, collect inside the work, evaluate what changed, then decide what changes next cycle.
The discussion below covers the wider evidence workflow around measurement and AI. Watch for where evaluation sits in the year; the design, not the software, still decides what your outcome data can support.
How do you explain why outcomes differed?
Read people’s open answers beside their outcomes to form questions about why results differ, then test those questions against the records; a pattern in comments is a lead, not a cause. Suppose graduates who were not placed often mention too little interview practice. That is worth investigating, not yet a finding.
Read the original answers, look for counter-examples and say which group the pattern describes. Count people and count comments separately, since they are different denominators. In Sopact Sense, an Intelligence Cell reads each open answer on arrival with a prompt your team configures, and people review the themes before they reach a report.
PROMPT · PASTE INTO CLAUDE, CHATGPT OR YOUR AI TOOL
I will paste one outcome definition with its time window, and a table with one row per person: ID, outcome (yes / no / unknown), training track, and their open answer to "What helped or got in the way?". No names.
1. Count yes, no and unknown, with the denominator.
2. Group the open answers into themes, separately for yes and no. For each theme give the number of people and two short quotes with their IDs.
3. List any theme that appears in both groups.
4. Suggest two questions worth checking against other records. Do not say what caused the outcome.
5. Use only the data I gave you. Do not invent numbers or quotes. If something is missing, write "not in our data".
What can an outcome evaluation not tell you?
It cannot, alone, tell you the program caused the change: a before-and-after difference is not proof without a comparison. Placement rates move with the local job market and with who enrolls, whatever the program does.
Self-reported outcomes carry recall and courtesy bias, and people who stop answering may be those for whom the program worked least or best. Outputs such as completions are not outcomes, however large. AI can count, theme and draft, but check every line against the records, and let a named person decide what the result means.
Start with one outcome this cycle
Choose the outcome your funder asks about most and evaluate it properly for one cohort before widening the scope.
- Write its dictionary entry: who counts, window, source, split, missing-value rule and owner.
- Test the entry on five real records with a colleague, and settle any disagreement.
- Make sure the first form issues each person an ID that every follow-up carries.
- Schedule the follow-up for when the change could have happened, such as 90 days after exit.
- Report placed, not placed and unknown against the planned denominator.
- Read the open answers of both groups and write one question to test next cycle.
After the first cycle you have one outcome with a definition two people count the same way, a per-person result with its unknowns, and one question to test next.
Frequently asked questions
What is the difference between outcome evaluation and impact evaluation?
Outcome evaluation describes what changed for participants, such as how many completers were placed in a job within 90 days of exit. Impact evaluation estimates how much of that change the program caused, which needs a comparison group or another counterfactual design. Many reports called impact evaluations are outcome evaluations; that is fine if the report names the design it used.
Does outcome evaluation prove that a program worked?
No. It shows whether intended outcomes were observed, for whom and how often. Other things, such as the local job market or who enrolled, can move the same numbers. A causal claim needs a design that estimates what would have happened otherwise and deals with rival explanations. Report outcomes plainly and keep any causal wording for evidence that supports it.
Must every outcome evaluation match the same people?
No. Matching is needed to describe individual change across waves. A post-program assessment or a repeated cross-section can answer other questions, such as whether a target was reached or how a population shifted, if the sampling and limits are stated. If you promise change per person, though, you need one ID carried from the first form to the last.
Does matched analysis solve attrition?
No. Matching describes the people who answered at every wave. People missing at follow-up may differ from those who stayed, so the matched result can still be biased. Report the unknown count beside the result, compare responders and non-responders on what you already hold, and never fill missing outcomes with an assumed value.
When should outcomes be measured?
When the intended change could reasonably have happened and the answer can still inform a decision. For a workforce program that means placement 90 days after exit and retention at 12 months, not the last session. Girls Inc. of Metropolitan Dallas pairs pre, mid and post surveys with follow-ups at six months and one year.
What are examples of outcome evaluation questions?
“How many completers were in paid work within 90 days of exit, and how many are unknown?” “Of those placed, how many held the same job at 12 months?” “Did starting wages differ by training track?” “Which groups were least likely to be placed, and what did they say got in the way?” Each names an outcome, a group and a window.