What is nonprofit impact measurement?
Nonprofit impact measurement is the planned collection and interpretation of evidence about what changed for the people or communities a nonprofit serves, judged against outcomes defined in advance, so the team can improve its work and report honestly. It covers what you delivered, what changed, for whom, and what you still do not know.
Most nonprofits measure for several readers at once: the program team, each funder and the board. The work turns heavy when each gets a separately built count.
THE SHORT VERSION
- Separate outputs, what you delivered, from outcomes, what changed for people, and write each outcome once with its time window.
- Collect once, into records that give each participant one ID at the first form, so intake, exit and every follow-up connect.
- Answer every funder from that one evidence base: their format and words, your records, and any difference in definition named in the report.
What is the difference between outputs and outcomes in nonprofit measurement?
Outputs count what your organization delivered; outcomes describe what changed for the people who took part. Enrollments, sessions and completions are outputs. A job still held a year after the program is an outcome.
The table uses Partner C, a fictional job-training program this guide follows throughout, whose funder’s theory of change runs from training to placement, retention and, in the long run, living-wage jobs.
Scroll horizontally to see all columns →
| Level | Partner C (fictional) | What the evidence supports |
|---|---|---|
| Inputs | Trainers, mentors, employer partners, grant funding | Resources used |
| Activities | Training and mentoring | What the team delivered |
| Outputs | Participants enrolled (unique people); completed training | Reach and delivery |
| Outcomes | Placed in a job within 90 days of exit; same job at 12 months; starting wage by track | Change seen among people you have evidence for |
| Impact | Living-wage jobs | A longer-term claim that needs longer evidence and attention to other influences |
Revenue and donations keep a nonprofit running, but neither shows the mission is working. The CDC evaluation framework separates checking whether outcomes were reached from judging whether a program caused them.
The short video below walks through the distinction. Watch for how a good outcome names who changed, what changed and by when; that wording becomes the definition you and your funders share.
Which methods can a nonprofit use to measure impact?
Pick the method by the question it answers: records for counts, repeated surveys on one ID for change, follow-ups for whether change lasted, open answers for why, outside data for context, and cost or value methods for resources. Most small programs need two or three of these six, not all of them.
Scroll horizontally to see all columns →
| Method | What it answers | Watch for |
|---|---|---|
| Program records | How many took part, who, how often | Unique people, not visits |
| Pre, mid and post surveys on one ID | How each person changed | Same wording and scale at every wave |
| Follow-ups (90 days, 12 months) | Whether change lasted or was used | Fewer people answer as time passes |
| Open answers and interviews | Why it changed | Quote with permission |
| Outside data on the same definition | How results sit next to a county figure or an earlier cohort | Different definitions do not compare |
| Cost per outcome or SROI | What a result cost, or what it is worth | Clear denominators and stated assumptions |
Frameworks organize these methods; they collect nothing. A theory of change or logic model sets out the pathway, Impact Frontiers’ Five Dimensions of Impact ask what, who, how much, contribution and risk, and IRIS+ offers standard metric codes.
Cost per outcome divides a defined cost by a defined count, such as cost per person placed within 90 days; it does not prove the program caused every result. Promise a social return on investment ratio only when your evidence supports a value, not only a count.
How do you measure impact when every funder asks for something different?
Collect once, into one set of records with one definition per metric, then give each funder its own format from those same records. Every funder gets its own report; none of them gets its own data collection.
Partner C reports to four readers: a quarterly template for Funder A, an annual narrative for Funder B, IRIS+ metrics for Funder C and a two-page board update. Collection is step 3 on the road below; measurement starts at step 4.
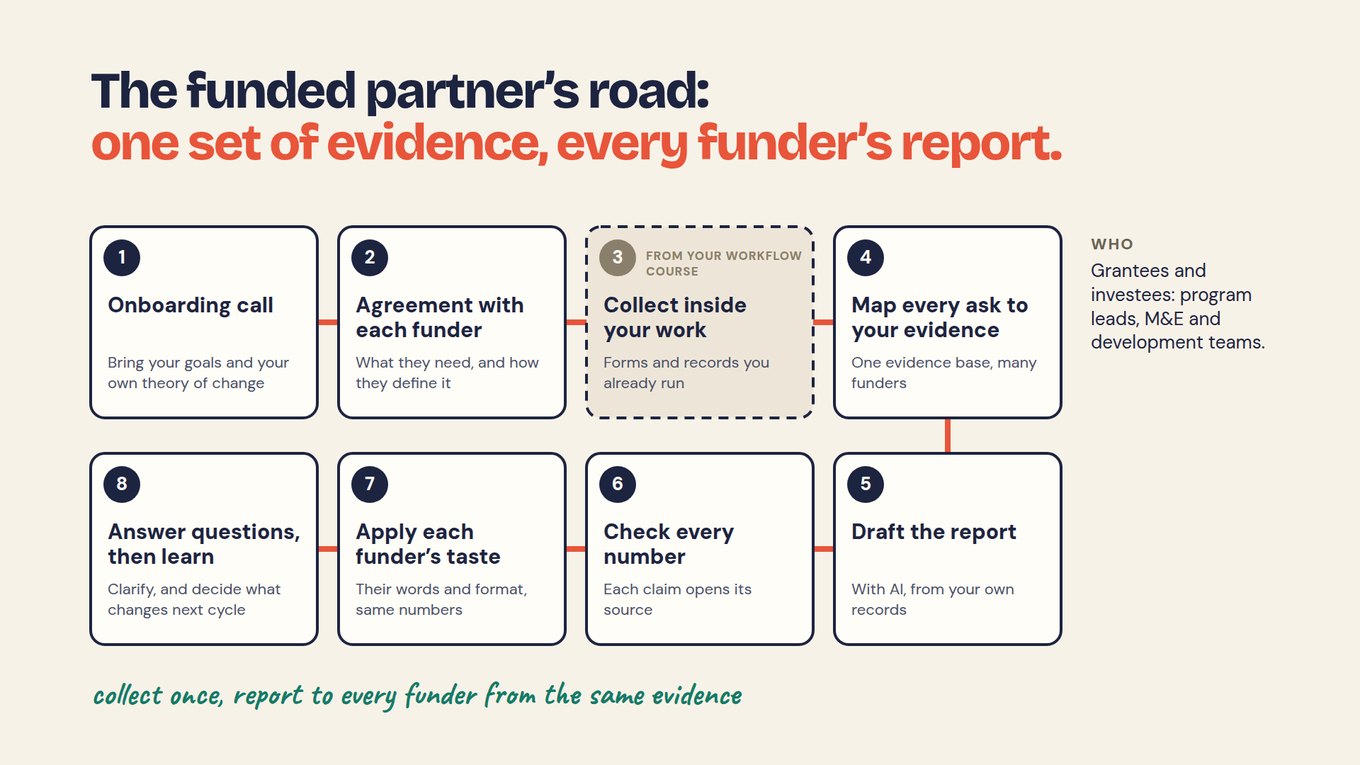
The tool for step 4 is a requirements map: one row per funder request, with their exact wording, the metric that answers it and any difference. The chapter Map every funder’s ask to one evidence base builds Partner C’s full map.
What should every nonprofit metric definition include?
Each metric needs one written definition that states what is counted, over which period or window, broken down how, and from which source. Without it, two people pull two different numbers from the same program.
A data dictionary holds those definitions, one row per metric. Partner C’s enrollment row reads “Total clients enrolled”: unique trainees in the reporting period, not sessions. Its dimensions are How much and Who, split by gender, age and disability, and its standard is IRIS+ PI4060, “Client Individuals: Total”.
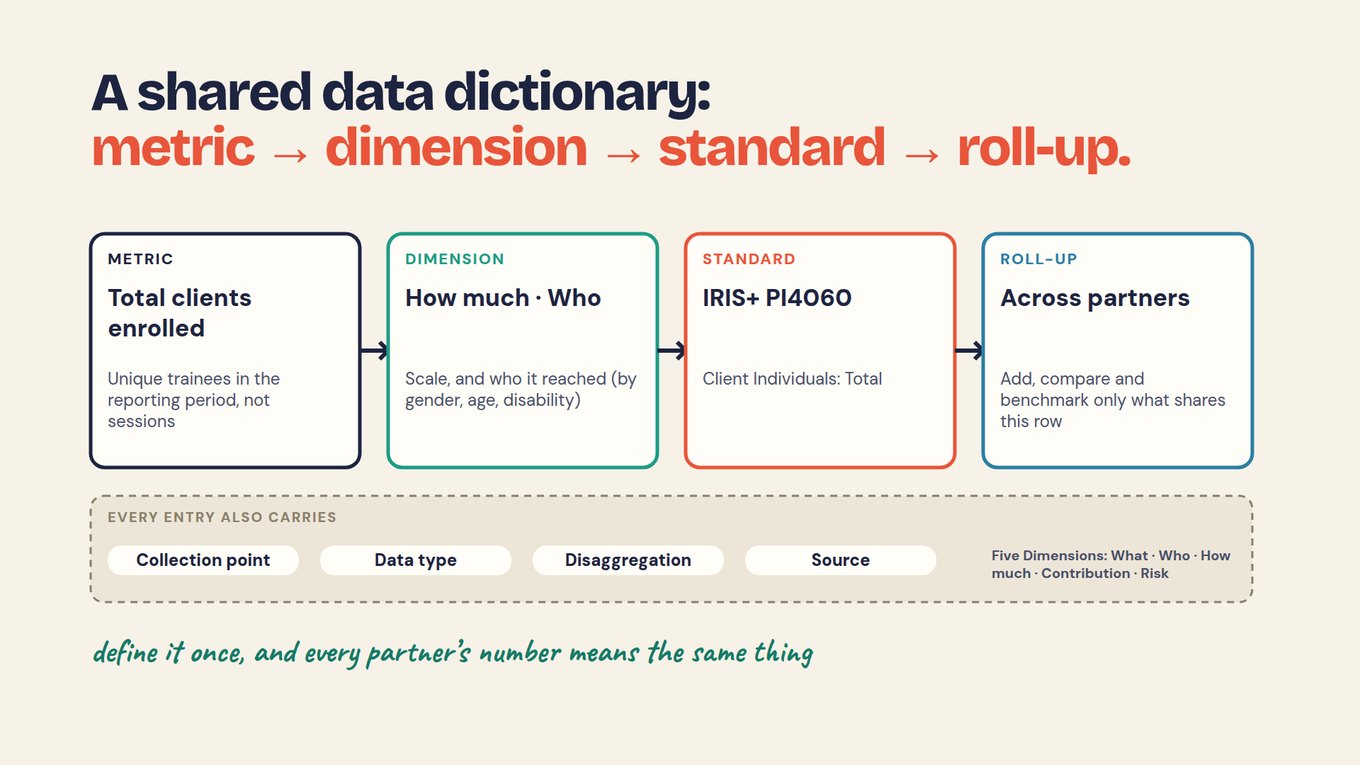
Outcomes need the same care: “placed in a job” means within 90 days of exit. When a funder defines a metric differently, report their number under their label with one sentence on the difference, and leave your dictionary as it is. The chapter A shared data dictionary shows how to fill each column.
What does a definition mismatch look like in a funder report?
It looks like a reasonable number that answers a different question. Partner C sent its funder, a fictional regional workforce fund with four job-training partners, 55 placements counted “within 6 months”, when the agreement said within 90 days of exit.
Checked line by line, enrollment matched at 80 unique people, placement used a different window, 12-month retention was missing, and starting wage came as one average, not split by track.
The other partners counted at 90 days, so the fund held C’s 55 out of the total and sent three questions: “Can you count placements within 90 days, as agreed?” “When will 12-month retention be available?” “Can you split starting wage by track?”
The first and third need no new collection when exit dates, placement dates and wages sit on one record per person; retention waits for the 12-month follow-up. A map row noting the six-month window would have caught the mix-up.
How do you track participant outcomes over time?
Give each participant one ID at the first form and attach every later survey, from mid-program to the one-year follow-up, to that same record. Change is a comparison of one person with their earlier self, and it breaks when each wave creates a new row.
Girls Inc. of Metropolitan Dallas runs a coding program with pre, mid and post surveys and follow-ups at 6 months and 1 year, on a reporting cycle tied to a July 1 fiscal year. Five waves only describe change when all five land on one participant.
Partner C’s retention metric has the same need: the exit record and the 12-month follow-up must belong to one person. Collect the finest detail once, such as exact age at intake, and group it each funder’s way at report time.
The Girls Inc. board asked hard questions about data privacy and AI before approving. In Sopact Sense, a persistent unique ID is issued at the first form, later workflows join the same record, and field selection keeps names and emails out of what AI receives. With any tool, the practice holds: one ID, created once, never retyped.
The video below contrasts disconnected snapshots, a survey in January, an interview in April and a report in December, with a pre and post survey on one record per participant. Watch for what becomes possible once each answer carries the same ID.
How can AI help draft a nonprofit measurement plan?
AI can draft the first pass of the plan from your agreements, templates and forms; a person then checks every definition against what each funder actually wrote. It reads long templates well, and it cannot know what a funder meant.
PROMPT · PASTE INTO CLAUDE, CHATGPT OR YOUR AI TOOL
You are helping a nonprofit write a one-page impact measurement plan for one program.

Inputs:
1. Our program description and theory of change: [PASTE]
2. Each funder's agreement or reporting template: [PASTE OR ATTACH]
3. Our forms and their fields (intake, exit, follow-up): [LIST]

Tasks:
- List our outputs and our outcomes separately. For each outcome, propose a definition: who is counted, the time window, the breakdowns.
- For each metric, name the form, field and wave that supply it.
- Quote which funders ask for each metric and flag any definition that differs from ours.

Rules: use only what these documents say. Do not invent numbers, targets or definitions. If something is missing, write "not in our data" and turn it into a question for our team. Return a table: Metric | Output or outcome | Definition | Source form and wave | Funders who ask | Gaps.
In Sopact Sense, the AI Assistant stays locked until you pick which surveys it may use, and each line of its answer links to a record you can open; Claude or ChatGPT can query the same data through MCP.
What can nonprofit impact measurement not prove?
It shows what changed among the people you have evidence for; on its own it does not show that your program caused the change. Outputs are not outcomes, and a before-and-after gain without a comparison group describes change rather than proving cause.
Placement and wage figures often come from self-report, and people who answer a 12-month follow-up may differ from those who do not. Put the number reached next to every percentage.
AI can draft the plan and the report, but people decide what the numbers mean; check each AI line against its record. For missing follow-up in depth, see outcome evaluation.
Start with one program and one funder report
Pick one program, one funder and one reporting cycle, and run the whole method once at small scale before adding anything.
- Write the program’s outputs and three to five outcomes, each with a time window, such as placement within 90 days of exit.
- Give each one a data dictionary row: definition, breakdowns, collection point and source.
- Check that the intake form issues one ID per person and that exit and follow-up forms carry it.
- Copy the funder’s asks word for word into a requirements map and mark each one same, different or no match.
- Draft the report from the records, name any difference in definition, and write “not yet available” where a window is still open.
- After the funder reads it, note their questions and fold the answers into the dictionary before the next cycle.
After the first cycle you hold one dictionary, one requirements map and a report whose numbers trace to records; the impact report template helps lay out the next one.
Frequently asked questions
How can a small nonprofit start measuring impact?
Choose one program and a few outcomes that matter to a real decision. Define each, with its time window and source, and make sure your intake form gives each person an ID that later forms carry. Run one reporting cycle, check who you reached at each wave, then add more.
Does impact measurement require tracking every person?
No. Following individuals suits the question of how each person changed, as with pre, mid and post surveys and follow-ups. Group, community and anonymous designs suit other questions, such as satisfaction with a public event. Match the design to the question, and say in the report what it can show.
How do we report to funders who define the same metric differently?
Keep one definition in your data dictionary and report each funder’s number under their definition, with one sentence on the difference. If Funder A counts visits and you count unique people, give visits in their field and unique people beside it. Changing your own records to match the latest template is how two reports end up disagreeing.
How often should a nonprofit collect outcome data?
Collect when the change could have happened. Learning can be measured at exit; placement needs a 90-day window and retention a 12-month follow-up. Funders’ quarterly or annual rhythms decide when you report, not when change occurs, and the ID on each record lets you place late follow-ups in the right period.
Can different sites use different surveys?
Yes, as long as they share the few metrics you compare. Agree one dictionary row per shared metric, map each site’s question to it, and let sites keep their local questions. Where two sites still count differently, report them side by side until the definition is settled.
What should nonprofit impact measurement software do?
It should give each participant one ID from the first form, attach every later survey to that record, and answer several funders from the same records. Test a full cycle with your own forms, a missing follow-up and two funders’ definitions, and check that each number traces to its records. See impact measurement software for the buying decision.