



What is an impact scorecard?
An impact scorecard is a one-page view of the metrics a funder and a funded partner agreed to track, showing for each metric what was reported, whether it matches the agreed definition, how it compares with the target, and what happens next. It lets a board or portfolio manager review progress without reading every report.
The page is short; the reasoning behind it should not be. A green cell means something only when the reader knows what was counted, for which period and why it earned that color, and “not yet comparable” is often more useful than a reassuring green.
THE SHORT VERSION
- Build the scorecard’s rows from the reporting agreement, so every row has a written definition before any number arrives.
- Give each reported number an evidence status first (matches, different, missing or not split), and score performance only where it matches.
- Turn every gap into one plain question to the partner, and let the portfolio total include only matching numbers.
Is an impact scorecard the same as a dashboard or an impact report?
No: a scorecard reviews a fixed set of results against what was agreed, a dashboard lets you explore patterns, and a report explains the work and its evidence to an audience. All three can draw on the same checked evidence.
Scroll horizontally to see all columns →
| Format | Main purpose | What it contains |
|---|---|---|
| Impact scorecard | Review results against the agreement | Metrics, results, status, target, action |
| Impact dashboard | Explore and monitor patterns | Views, filters, trends, detail |
| Impact report | Explain work and evidence to readers | Methods, findings, context, limits, story |
A dated board document can be as trustworthy as a live view if its “data through” date, calculation and sources are clear. Being live does not make a number more accurate.
What statuses should an impact scorecard use?
Use two kinds of status and keep them apart: an evidence status that says whether a number can be compared at all, and a performance status that says how it compares with the target. Mixing them is the most common scorecard mistake.
The evidence status has four values, taken from the check in the course: matches (same metric, same definition, same period), different definition, missing, and not split (one number where the agreement asks for a breakdown). Only a match gets a performance status; everything else gets a question.
Keeping them apart stops two errors. A partner is not failing because its follow-up is late, and a partner is not succeeding because the easiest people to reach answered well.
What does a scorecard look like for one funded partner?
Take one partner report, lay it beside the agreement, and give each metric its evidence status; the gaps become the partner’s questions. The example is fictional: a regional workforce fund that funds four job-training partners, A to D, and Partner C’s report has arrived.
The agreement counts enrolled as unique people, placement within 90 days of exit, retention in the same job at 12 months, and hourly starting wage by track. Partner C reported 80 people enrolled, which matches. It counted placements within six months, left out retention, and gave one average wage.
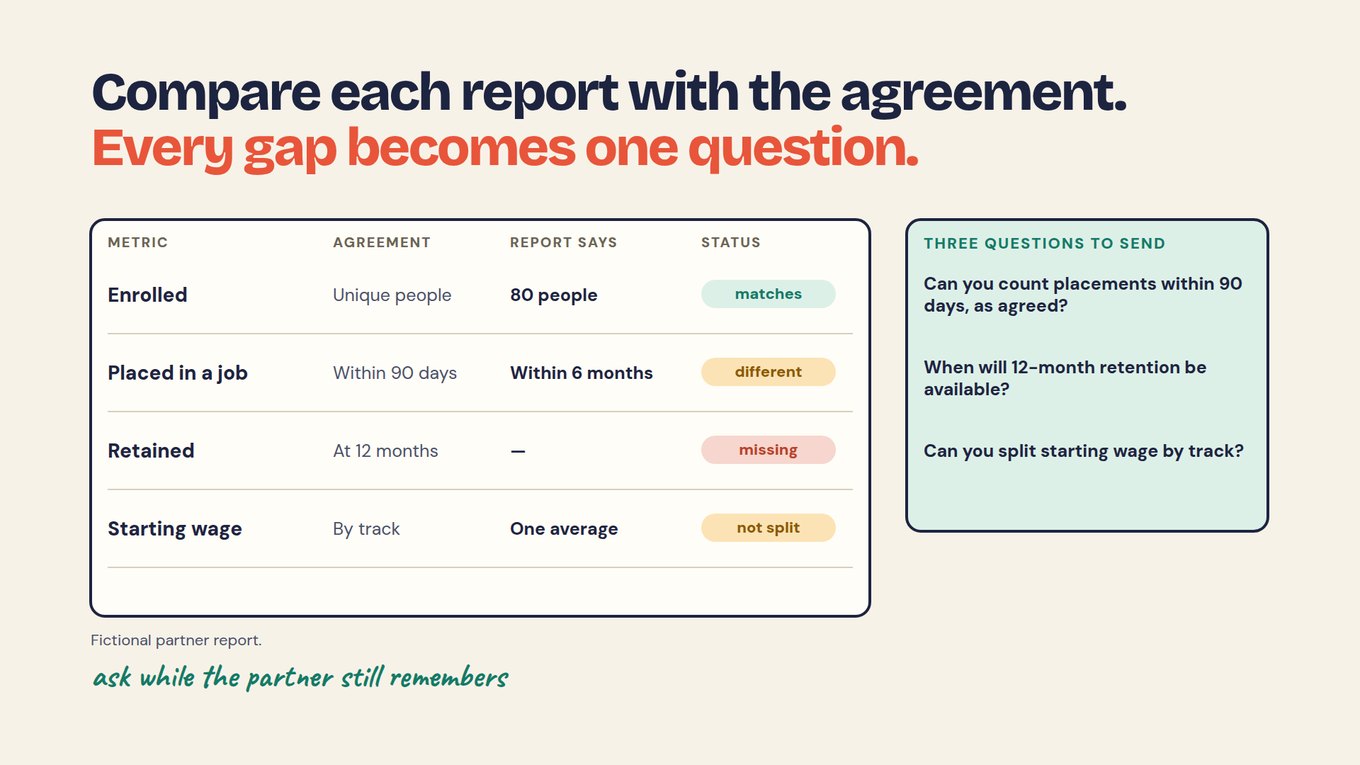
None of the three gaps says anything about performance. Partner C may have placed more people than anyone; you cannot tell yet, because its count uses a different window. The chapter Check each partner report against the agreement covers writing the questions and keeping the gap log.
What goes in an impact scorecard template?
Each row needs eight fields, from the metric’s definition to the next action and its owner; the main view shows a few, and the rest sit in a note one click away. Copy the first two columns into a spreadsheet; the third shows Partner C’s placement row filled in.
Scroll horizontally to see all columns →
| Field | What to write | Partner C example |
|---|---|---|
| Priority | The outcome the row serves | Trainees move into work |
| Metric | Name, unit, who counts, window | Completers in paid work within 90 days of exit |
| Reference | Agreed target or earlier result | The grant’s target, as agreed |
| Finding | Result, period, denominator, data-through date | 55 placed, counted within 6 months |
| Evidence status | Matches, different, missing or not split | Different definition |
| Performance status | Against the reference, only if it matches | Not scored yet |
| Action and owner | Decision or question, who, by when | Ask for the 90-day count; portfolio manager |
| Evidence note | Source, calculation, main limitation | Partner C’s report; follow-up is self-reported |
The evidence note is where trust comes from. A board reader gets a plain explanation; an authorized analyst can open the underlying records. Nobody needs participant names on the scorecard itself.
Where should the scorecard’s definitions come from?
Every scorecard row should point to one row of a shared data dictionary, written before the first report and sent to every partner. Without it, the same word gets counted differently by each partner and the scorecard compares unlike things.
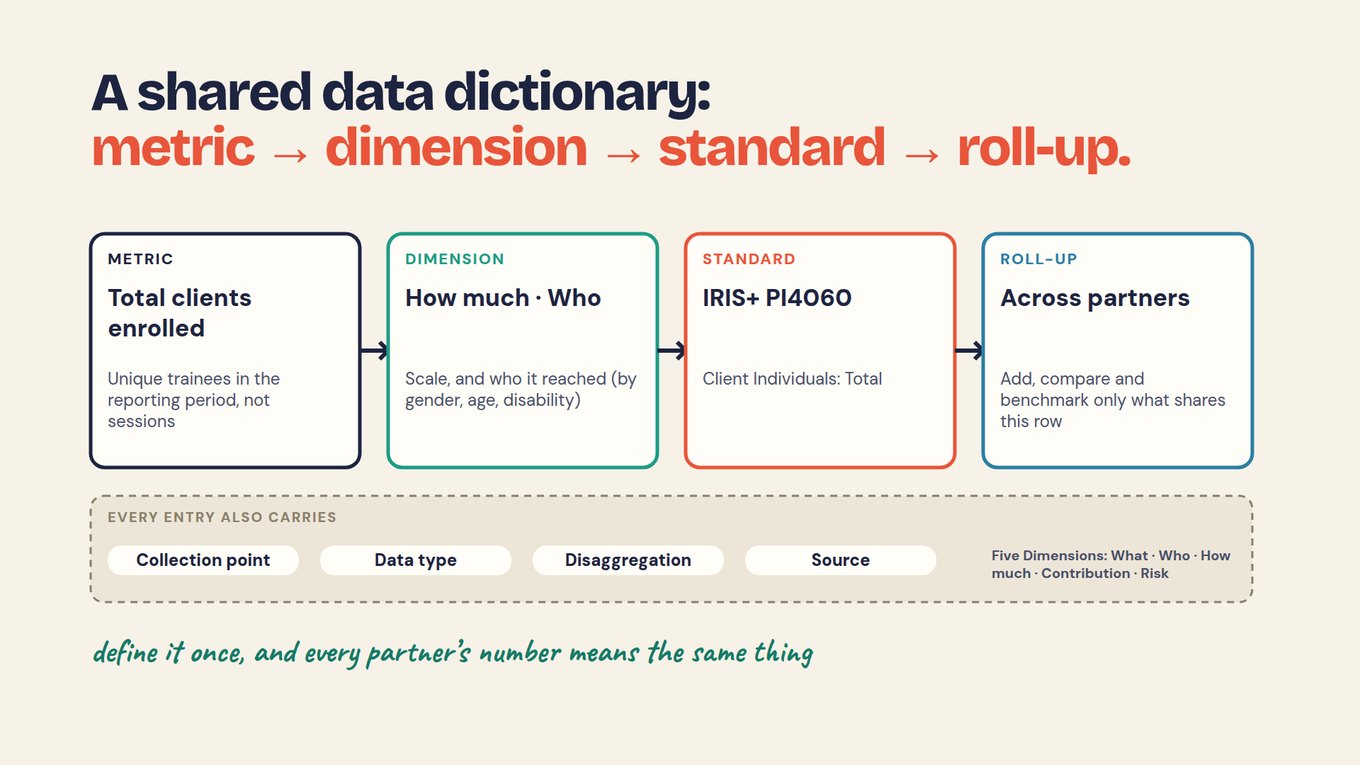
Portfolio funders write these at the start. AHA Ventures, the investment arm of the American Heart Association, is growing its portfolio from 19 to more than 40 companies; its head of impact drafts each company’s logic model and data dictionary during the onboarding call, with Sopact Sense. For choosing the metrics themselves, see social impact metrics.
How do you build a portfolio scorecard across partners?
Put partners in rows and agreed metrics in columns, show each cell’s evidence status beside its number, and let the portfolio total include only the matches. Held numbers stay on the page, each with a one-line reason.
Scroll horizontally to see all columns →
| Partner | Reported | Evidence status | In the total? |
|---|---|---|---|
| A | 42 | Matches | Yes |
| B | 31 | Matches | Yes |
| C | 55, within 6 months | Different definition | Held; question sent |
| D | 27 | Matches | Yes |
| Portfolio | 100 (42 + 31 + 27) | From A, B and D | C added once confirmed |
When C confirms, its 90-day count joins the total; that count can be no higher than 55, since every placement within 90 days also falls within six months. For rates, combine the underlying counts and denominators rather than averaging each partner’s percentage. Partners serve different people in different places, so use the grid to start conversations, not to rank. More in Roll up and benchmark portfolio results.
How do you build an impact scorecard, step by step?
Start from the decision the scorecard serves, take its rows from the agreement, set the status rules before results arrive, and give every finding an owner. Five steps cover it.
- Name the review decision: continue a grant, support a partner, change delivery or review expansion.
- Take the rows from the agreement: delivery measures beside outcomes, each with its dictionary definition.
- Set status rules in advance: where each target came from, and when a gap blocks a performance status.
- Connect source and calculation: period, numerator, denominator and the report each number came from.
- Add the action and owner: a decision or an explicit reason to wait, with the next review date.
Do not rewrite a target after seeing the result without recording why. The video below, Output vs Outcome: 7 Rules to Measure What Actually Changed, helps with step 2: watch for the line between an output, which counts what was delivered, and an outcome, which shows what changed, and check that your rows include both.
PROMPT · PASTE INTO CLAUDE, CHATGPT OR YOUR AI TOOL
Build a scorecard row for each metric in our agreement,
using this partner's report.

Agreement (metric, definition, period, breakdown, target):
[PASTE AGREEMENT TABLE]

Partner report:
[PASTE OR ATTACH REPORT]

For each agreed metric return: metric, reported value with
where you found it, evidence status (matches, different
definition, missing, not split), performance status against
the target ONLY if the status is "matches", and one plain
question for the partner if it is not.

Rules:
- Do not calculate, convert or estimate any value.
- If a value is not in the report, write "not in our data".
- A similar metric is not a match; say how it differs.
What should you ask of impact scorecard software?
Test a full review cycle with messy data, including a late report, a changed definition and a missing follow-up, rather than judging from a screenshot. Many dashboard and database tools can do this when configured; the question is the effort and control your whole workflow needs.
Scroll horizontally to see all columns →
| Test | What to look for |
|---|---|
| Behind a number | Definition, denominator, period and status one click away |
| Changed definition | Shown as a change, not as a change in performance |
| Local forms | Partner forms map to shared metrics without extra questions |
| Access | Reviewers open records; others see summaries |
| Reproduce | Someone can rebuild a headline and state its limit |
In Sopact Sense, each partner’s data can sit in its own folder, with that team’s AI Assistant seeing only its folder and the portfolio owner seeing aggregated results, and every line of an Assistant answer links to a record you can open. Test it on your own messy cycle like any other tool.
What can an impact scorecard not tell you?
A scorecard tells you whether a number can be compared and how it sits against a target; it cannot show that the program caused the change. A clean match can sit in a weak program, and a gap can come from a strong one.
Completion is an output, not an outcome. Placement and retention usually rest on self-reported follow-up, and the people who answer may differ from those who do not. If an AI tool drafts the rows, a person checks each against the report before any question goes out under your name.
Start with one partner’s scorecard this period
Build the scorecard for one partner report before designing a portfolio view.
- Copy the agreement’s metrics into the first column, each with its dictionary definition.
- Read the partner’s report against each row and give it an evidence status.
- Score performance only on the matches, against the agreed target.
- Write one plain question per gap and send them together within a week.
- Record each answer, update the row, and note any definition that more than one partner read differently.
After the first cycle you have one partner’s scorecard, a short gap log, and the rows a portfolio scorecard can reuse for every other partner.
Frequently asked questions
What makes an impact scorecard trustworthy?
Written definitions behind every row, an evidence status beside every number, targets set before the results arrived, and a note showing where each number came from and its main limitation. A reader who asks “counted how?” or “from which report?” should get an answer in one click. Color alone never makes a scorecard trustworthy; the reasoning behind the color does.
Does every impact scorecard need live data?
No. Match the update rhythm to the decision and the metric. Enrollment can be quarterly, while 12-month retention cannot exist until a year has passed. A dated, reviewed snapshot is often right for a board. If a view updates continuously, show a data-through date and keep the figures used in an issued report so you can explain why today’s number differs.
Should board members see participant names behind every metric?
Not usually. Board members need enough evidence to understand and challenge a finding: the definition, the denominator, the source report and the main limitation. Identifiable records should be open only to the roles that need them. A de-identified evidence note beside the row is usually enough for board review.
How many metrics should an impact scorecard include?
As many as the agreement requires and no more. The fictional workforce fund tracks five: enrolled, completed training, placed within 90 days, retained at 12 months and starting wage by track. That set mixes delivery and outcomes and fits on one page. A scorecard that tries to serve every audience becomes too large to use.
Can we average results across programs or partners?
Only when every part shares a definition, population and period. For a rate, add the underlying counts and denominators; an average of percentages answers a different question. Numbers counted another way, such as placements within six months beside placements within 90 days, stay out of the total and appear beside it with a note.
Is an impact scorecard proof of impact?
No. It summarizes selected evidence against what was agreed. It can show that placements matched the agreed definition and beat a target, not that the program caused them. A causal claim needs a comparison designed for it, such as earlier cohorts counted the same way, and even then self-report and non-response limit what you can say.
