


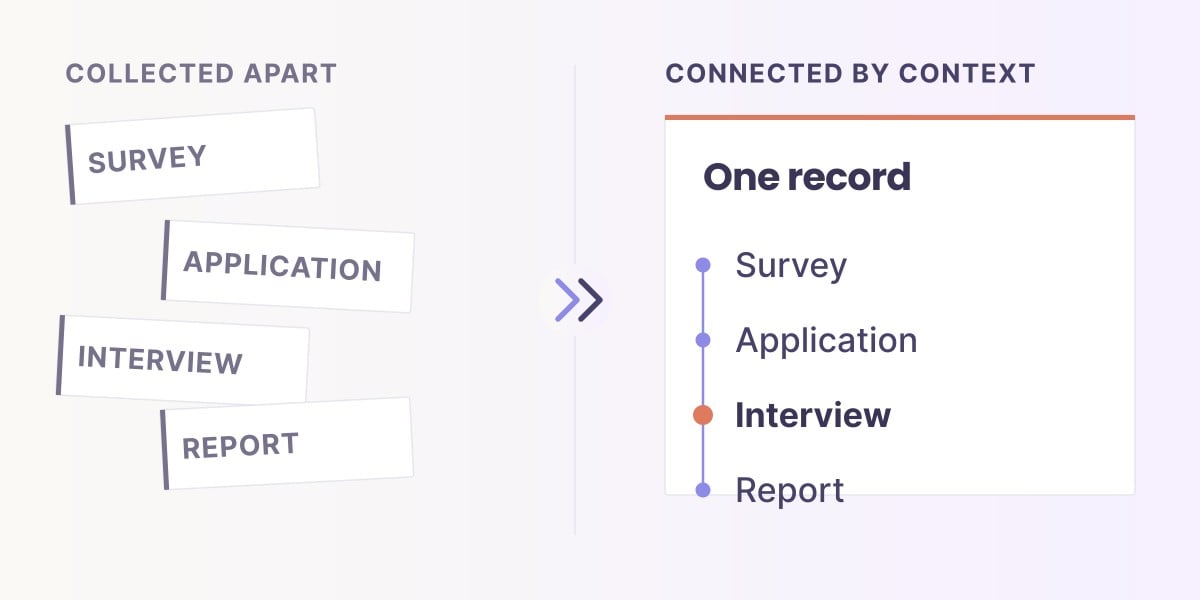
What is impact evaluation?
Impact evaluation estimates the change a program caused by comparing what happened to participants with a credible estimate of what would have happened to them without the program, called the counterfactual. Terms vary by field, so name the causal question and the design rather than relying on the label.
Nobody can observe the counterfactual directly, because the same people cannot both join and skip a program. Every design is a way of building a stand-in for it, and each stand-in rests on an assumption you should be able to state in one sentence.
THE SHORT VERSION
- An impact evaluation needs a comparison that stands in for life without the program; a rise from before to after is not one.
- Random assignment, difference-in-differences, matching and other designs build that comparison in different ways, each on an assumption you must check.
- A program team can fix definitions, keep one record per person and compare with outside data on the same definition; sizing the effect usually needs an evaluator.
How is impact evaluation different from monitoring and outcome evaluation?
Monitoring tracks agreed metrics during the year, outcome evaluation asks what changed for participants, and impact evaluation asks how much of that change the program caused. Each builds on the one before, so a weak monitoring record limits every evaluation after it.
| Type | Question | Evidence it needs | Who leads |
|---|---|---|---|
| Monitoring | Are we on track against the agreement? | Agreed metrics, collected all year | Program team |
| Outcome evaluation | What changed, and for whom? | The same people measured over time | Program team, often with a reviewer |
| Impact evaluation | How much change did the program cause? | A comparison group or other counterfactual design | Evaluator, with the program team |
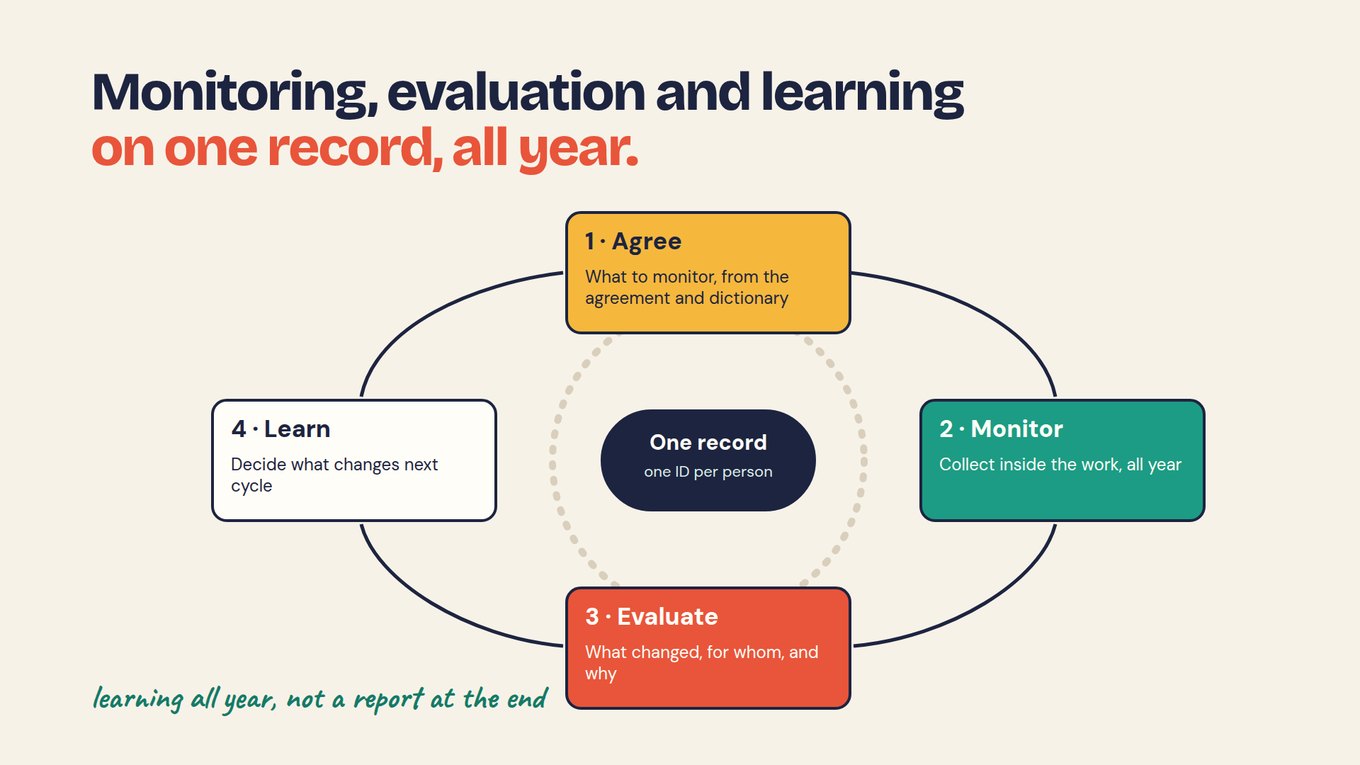
In a monitoring, evaluation and learning loop, you agree what to monitor from the reporting agreement and data dictionary, collect inside the work all year, evaluate what changed, for whom and why, then decide what changes next cycle. Impact evaluation is the deepest form of that third stage, and it only works if the first two kept one record per person.
The short video below separates outputs from outcomes, the distinction every impact evaluation rests on. Watch for how an outcome is worded so it can be measured the same way twice; an effect estimate is only as sound as that definition.
Why isn’t a before-and-after change enough?
Because other things move at the same time: the job market, who enrolled, how the outcome was counted and people’s own progress can all change a before-and-after number without any help from the program. The comparison has to separate those from the program’s part.
Sopact’s course follows a fictional regional workforce fund and its four job-training partners. This year, Partners A, B and D placed 100 people in a job within 90 days of exit. If next year’s count is higher, hiring may have picked up across the region, or a partner may have enrolled people who were already closer to work.
The count itself can shift too. Partner C reported 55 placements using a six-month window instead of the agreed 90 days; a change like that, unnoticed, looks like a rise in results. People who enroll at a low point also tend to improve anyway, a pattern called regression toward the mean.
What are the main impact evaluation designs?
Five quantitative designs cover most impact evaluations of social programs; each builds the counterfactual a different way and each depends on an assumption that can fail. The last column shows what each might look like for the workforce fund.
| Design | Basic idea | Assumption or limit | For the workforce fund |
|---|---|---|---|
| Randomized comparison | A lottery decides who gets a place | Attrition and spillovers still matter | Oversubscribed places filled by lottery |
| Difference-in-differences | Compare changes over time across groups | Both groups were on parallel trends | Trainees vs similar job seekers, before and after |
| Regression discontinuity | Compare people near an assignment cutoff | Only the program changes at the cutoff | An eligibility score decides entry |
| Matching or adjustment | Compare with people alike on measured traits | Unmeasured differences can still bias it | Match on age, prior work and education |
| Interrupted time series | Look for a break in a repeated series | Nothing else changed at the break | Monthly placements before and after new mentoring |
Work with an evaluator who can judge feasibility, sample size and assumptions; a sophisticated method on unsuitable data does not produce a credible estimate. The World Bank’s Impact Evaluation in Practice explains counterfactuals and these designs in more depth.
The video below compares two of the designs most teams weigh, following the same people over time or comparing groups at one point, and asks which one a funder will accept as evidence that the program caused the change.
What do interviews and theory-based evidence add?
They explain how and why an effect happened, or did not, which a single estimate cannot show. Interviews, observation and documents can reveal whether mentoring reached people, why one partner placed more graduates, or where an expected link broke.
Theory-based approaches such as contribution analysis test the program’s pathway against rival explanations, and they need the same discipline as a statistical design. A positive story assembled from supportive quotes is not evidence of effect. The guide to attribution vs contribution covers that approach step by step.
What can a program team do without an evaluator?
A program team can do the groundwork that decides whether an impact evaluation is possible at all: agreed definitions, one record per person, honest follow-up counts and comparisons on the same definition. Sizing the effect is the evaluator’s job.
| Task | Program team | Evaluator |
|---|---|---|
| Define outcomes and time windows | Leads, in the agreement and dictionary | Reviews |
| Keep one ID per person across waves | Leads | Depends on it |
| Count who is missing at follow-up | Leads | Adjusts for it |
| Compare with earlier cohorts or outside data | Leads, labelled as context | Advises |
| Choose a comparison group | Contributes | Leads |
| Estimate the effect and its uncertainty | Reviews | Leads |
Definitions come first. “Placed in a job” means within 90 days of exit and “retained” means the same job at 12 months; write both in a shared data dictionary before collection, or no later comparison will hold.
In Sopact Sense, a persistent unique ID from the first form links each person’s intake, placement and follow-up answers on one record, so an evaluator starts from matched records rather than merged spreadsheets. Public data loaded as an ordinary survey follows the same rules as your own.
How can outside data help, and where does it stop?
Outside data on the same definition gives your result a fair reference point, such as the local wage for the same job, but it describes other people, not your participants without the program. Treat it as context beside your results.
The fund’s agreement asks for starting wage, hourly, by track. Each track trains for an occupation with a standard code, and the Bureau of Labor Statistics publishes hourly wages by occupation and area. Since new hires start low, set graduates beside the 25th percentile as well as the median, and name the area and reference year.
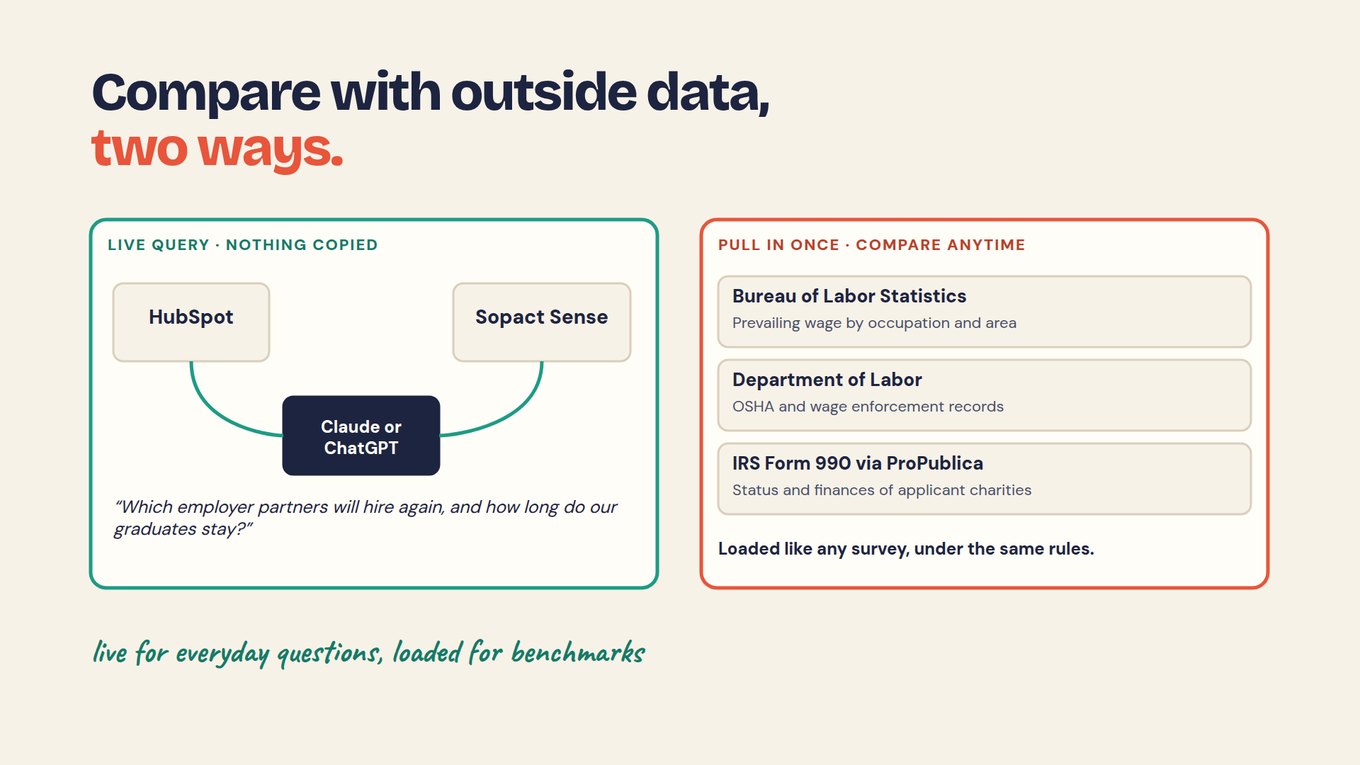
A comparison is fair only when both numbers count the same thing, for the same kind of people, place and period. Partner C’s single average starting wage cannot join the comparison, because it mixes tracks. The chapter Compare your results with outside data shows how to write both definitions in one row first.
Where it stops: graduates earning above the local 25th percentile is worth reporting, but people who enroll may differ from the typical worker in that job. Only a design that compares similar people can say what the program added.
How do you plan an impact evaluation with an evaluator?
Plan before enrollment opens, because most designs need the comparison group, the baseline and the outcome windows fixed before the first participant arrives. A design added after the fact usually falls back to before-and-after.
Check that the design is feasible, fair to participants and useful for a real decision; never delay needed support to create a convenient comparison. Write down outcomes and analysis choices in advance, keep negative findings, and record any change to the plan.
PROMPT · PASTE INTO CLAUDE, CHATGPT OR YOUR AI TOOL
Help me prepare a one-page brief for an evaluator. Our program: [WHAT WE DO, FOR WHOM, WHERE]. The decision the evaluation should inform: [DECISION]. Our outcome definitions, with time windows: [DEFINITIONS]. What we collect today, and when: [SOURCES AND WAVES]. Follow-up counts so far: [INVITED, ANSWERED]. No names.
1. Write the causal question in one sentence.
2. List two or three designs that might fit, with the assumption each depends on and what would make it infeasible for us.
3. List what we must collect or fix before enrollment for each design.
4. List the questions we should ask the evaluator.
5. Use only facts I gave you. Do not invent numbers, sample sizes or effects. Where information is missing, write "not in our data".
What can you conclude from an impact evaluation, and how should you say it?
State the population, the comparison, the outcome, the period and the uncertainty, and keep observed change and estimated effect in separate sentences. Say whether it would hold in another setting.
Hold the limits in view as you write. Outputs such as sessions delivered are not outcomes. A before-and-after change is not proof of cause without a comparison. Self-reported answers carry recall and courtesy bias, and the people who stop answering follow-ups may be the ones for whom the program worked least.
AI can organize source material and draft wording, but it cannot supply a missing counterfactual or rescue an unsupported claim. Check every line it writes against the records, and let a named person decide what the evaluation concludes. For the wider planning process, see program evaluation.
Start with one evaluation question this year
Pick one outcome a funder or board keeps asking about, and get it ready for an impact evaluation, whether or not you commission one this year.
- Write the causal question: which outcome, for whom, over what period, compared with what.
- Check that the outcome has one definition and time window in your agreement and dictionary.
- Make sure each participant carries one ID from the first form to the last follow-up.
- Count invited, answered and missing at each follow-up, and look at who is missing.
- Find one outside figure or earlier cohort on the same definition, and label it as context.
- Run the prompt above and take the brief to one evaluator for a conversation.
After the first cycle you have a sharp causal question, matched records, one honest comparison and a view of which design, if any, is within reach.
Frequently asked questions
What is a counterfactual in impact evaluation?
The counterfactual is what would have happened to participants without the program. It can never be observed directly, since the same people cannot both take part and not take part. Evaluations estimate it with a comparison: a randomly assigned control group, a matched group, people near an eligibility cutoff or a trend before the program started. The credibility of the whole result rests on that comparison.
Is outcome evaluation the same as impact evaluation?
No. Outcome evaluation describes what changed for participants, such as how many were placed in a job within 90 days of exit. Impact evaluation asks how much of that change the program caused, which needs a comparison. Many reports labelled impact evaluations are outcome evaluations; that is fine, as long as the report states the design it actually used.
Are randomized trials always possible?
No. Random assignment needs more applicants than places, enough people for a stable estimate and a setting where a lottery is fair. It may be wrong to withhold a service people urgently need. Where a trial does not fit, difference-in-differences, regression discontinuity or matching may, each with its own assumptions stated openly.
When is a program ready for an impact evaluation?
When delivery is stable, outcomes have agreed definitions and time windows, each participant carries one ID across waves, and follow-up reaches most people. A program still changing its model every quarter is better served by monitoring and outcome evaluation first. Evaluating too early measures an unfinished program.
Can qualitative evidence support causal claims?
Yes, when it is gathered systematically to test the program’s pathway and rival explanations. Interviews can show whether mentoring reached people and why results differed across partners. It should include people with poor outcomes and should not be reduced to selected testimonials. Many evaluations combine it with a quantitative design.
Does AI make an evaluation causal?
No. Causal credibility comes from the question, the design, the evidence and the assumptions, not from the tool that summarizes the data. AI can help organize records, theme open answers and draft a brief for an evaluator. A person still needs to check each output against the source records and decide what the evaluation can conclude.
